Appearance
Awesome Spring AI
Getting Started with MCP
了解 Model Context Protocol (MCP)
模型上下文协议(MCP)规范了人工智能应用与外部工具和资源的交互。
Spring早早地加入了MCP生态系统的贡献者行列,作为关键参与者,帮助制定并维护了 t="C0"> 官方的MCP Java SDK ,这是基于Java的MCP实现的基础架构。 在这一贡献的基础上,Spring AI通过启动脚本和注解的方式,为MCP提供了支持,使得构建MCP服务器和客户端变得更加容易。
引言视频
请开始此处,为模型上下文协议(Model Context Protocol, MCP)提供一个简要介绍,解释其核心概念和架构。
完整教程及源代码
📖 Blog Tutorial: 连接您的AI到无处不在
💻 完整源代码: MCP天气示例仓库
该教程涵盖了使用Spring AI进行MCP开发的要点,包括高级功能和部署模式。以下是具体内容: 所有代码示例均来自本教程。
快速开始
快速上手的最佳方法是使用Spring AI的注解式开发方法。以下示例来自博客教程:
简单MCP服务器
java
@Service
public class WeatherService {

    @McpTool(description = "Get current temperature for a location")
    public String getTemperature(
            @McpToolParam(description = "City name", required = true) String city) {
        return String.format("Current temperature in %s: 22°C", city);
    }
}
请添加依赖项并配置:
xml
<dependency>
    <groupId>org.springframework.ai</groupId>
    <artifactId>spring-ai-starter-mcp-server-webmvc</artifactId>
</dependency>
properties
spring.ai.mcp.server.protocol=STREAMABLE简单MCP客户端
这是一个简单的MCP(消息客户端协议)客户端。
简单MCP客户端
java
@Bean
public CommandLineRunner demo(ChatClient chatClient, ToolCallbackProvider mcpTools) {
    return args -> {
        String response = chatClient
            .prompt("What's the weather like in Paris?")
            .toolCallbacks(mcpTools)
            .call()
            .content();
        System.out.println(response);
    };
}
请添加依赖项并配置:
xml
<dependency>
  <groupId>org.springframework.ai</groupId>
  <artifactId>spring-ai-starter-mcp-client</artifactId>
</dependency>
yaml
spring:
  ai:
    mcp:
      client:
        streamable-http:
          connections:
            weather-server:
              url: http://localhost:8080
学习资源
实现视频
Spring AI 模型上下文协议(MCP)集成 - YouTube
展示Spring AI MCP集成的视频演示,涵盖服务器和客户端实现。
Additional Examples 仓库
超越教程示例, Spring AI示例 存储库包含众多MCP实现。
推荐开始点
基于注解的示例
By Use Case
天气服务:
数据集成:
Web整合:
客户端示例:
社区资源
- Awesome Spring AI(社区示例和资源) - Community examples and resources
- 官方MCP规范
- 官方MCP Java SDK - 由Spring团队开发的Java SDK
- MCP Java SDK 文档
Dynamic Tool Discovery
动态工具发现,使用工具搜索工具
随着AI代理连接到更多服务——如Slack、GitHub、Jira和MCP服务器——工具库迅速增长。一个典型的多服务器设置可能会有超过50个工具在任何对话开始前消耗大量token。更糟糕的是,当模型面临30多个同名工具时,工具选择的准确性会下降。
The 工具搜索工具 模式, 由Anthropic倡导 ,解决了这一问题:它不是一开始就加载所有工具定义,而是模型在需要时动态发现工具。它只提供一个搜索工具,当需要时查询能力,然后根据需要扩展相关的工具定义。
Spring AI的实现实现了在OpenAI、Anthropic和Gemini模型中34%至64%的token减少,同时保留了数百个工具的完全访问权限。
简介
The 工具搜索工具 项目扩展了Spring AI的 递归顾问 ,以实现跨 任何大语言模型提供商 的动态工具发现功能。
关键优势:
- Token'E economic gain - 只有发现的工具定义会被发送到LLM中
- 提升准确性 - 模型能够更可靠地从更小、相关的一组工具中选择合适的工具
- 可扩展性 - 管理成百上千的工具,无需受上下文膨胀影响
- portability - 与 OpenAI, Anthropic, Gemini, Ollama, Azure OpenAI 等更多服务兼容
博客文章
📖 全教程: 智能工具选择:利用Spring AI的动态工具发现实现34-64%的Tokens节省
博客文章详细介绍了完整实现细节、性能基准测试以及高级使用场景。
快速开始
依赖项
在你的项目中添加一个依赖项:Tool Search Tool。
- Maven
- Gradle
xml
<dependency>
    <groupId>org.springaicommunity</groupId>
    <artifactId>tool-search-tool</artifactId>
    <version>2.0.0</version>
</dependency>

<!-- Choose a search strategy -->
<dependency>
    <groupId>org.springaicommunity</groupId>
    <artifactId>tool-searcher-lucene</artifactId>
    <version>2.0.0</version>
</dependency>| Version v1.0.x 是 Spring AI 1.1.x / Spring Boot 3 相容的版本。Version v2.0.x 是 Spring AI 2.x / Spring Boot 4 相容的版本。 |
|---|
基本用法
java
@SpringBootApplication
public class Application {

    @Bean
    CommandLineRunner demo(ChatClient.Builder builder, ToolSearcher toolSearcher) {
        return args -> {
            var advisor = ToolSearchToolCallAdvisor.builder()
                .toolSearcher(toolSearcher)
                .build();

            ChatClient chatClient = builder
                .defaultTools(new MyTools())  // 100s of tools registered but NOT sent to LLM initially
                .defaultAdvisors(advisor)     // Activate Tool Search Tool
                .build();

            var answer = chatClient.prompt("""
                Help me plan what to wear today in Amsterdam.
                Please suggest clothing shops that are open right now.
                """).call().content();

            System.out.println(answer);
        };
    }

    static class MyTools {
        @Tool(description = "Get the weather for a given location at a given time")
        public String weather(String location,
            @ToolParam(description = "YYYY-MM-DDTHH:mm") String atTime) {
            // implementation
        }

        @Tool(description = "Get clothing shop names for a given location at a given time")
        public List<String> clothing(String location,
                @ToolParam(description = "YYYY-MM-DDTHH:mm") String openAtTime) {
            // implementation
        }

        @Tool(description = "Current date and time for a given location")
        public String currentTime(String location) {
            // implementation
        }

        // ... potentially hundreds more tools
    }
}
如何工作
The 零 extends Spring AI’s 一 to implement dynamic tool discovery:
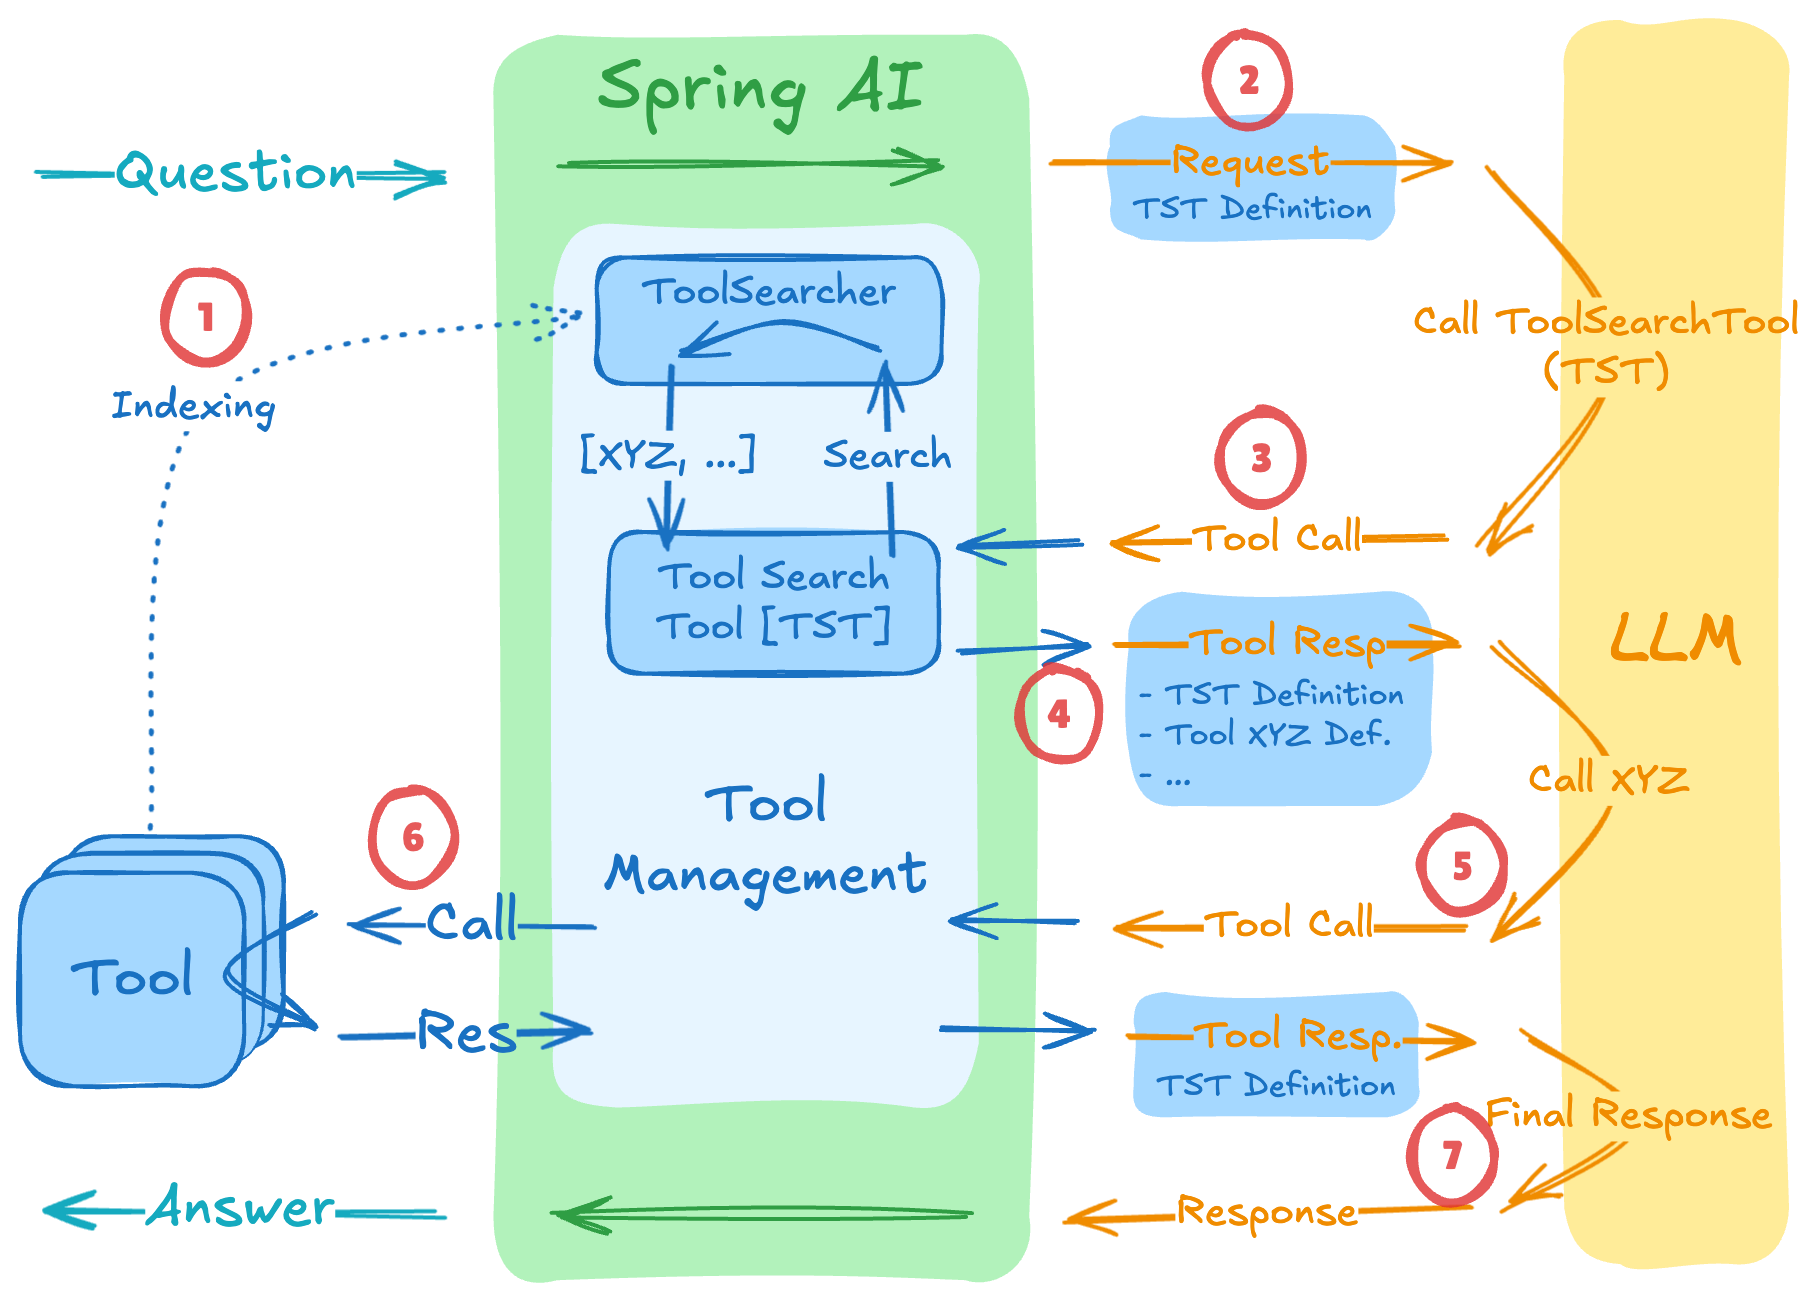
- 索引: 在对话开始时,所有注册的工具都会在
ToolSearcher中进行索引(但不会发送给大语言模型) - Initial Request: 只将工搜索工具定义发送至LLM
- 发现调用: 当LLM需要能力时,它会通过搜索工具发送查询
搜索与扩展
: TheToolSearcherfinds matching tools and their definitions are added to the next request- 工具调用: LLM现在能够识别并调用搜索工具和发现的工具定义
- 工具执行: 发现的工具被执行,结果被返回
- 响应: LLM生成最终答案
搜索策略
The ToolSearcher interface supports multiple search implementations:
| 策略模式 | 实现 | 最适合 |
|---|---|---|
| 语义 | VectorToolSearcher | 自然语言查询,模糊匹配 |
| 关键字 | LuceneToolSearcher | 精确术语匹配,已知工具名称 |
| 正则表达式 | RegexToolSearcher | 工具名称模式( get_*_data ) |
See 工具搜索者 查看所有可用实现。
性能
初步基准测试结果表明,使用28种工具显著节省了Tokens数量:
| 模型 | 基于工具搜索 | 没有 | 储蓄 |
|---|---|---|---|
| 双子座 | 2,165 tokens | 5,375 个标记 | 60% |
| OpenAI | 4,706 tokens | 7,175个token | 34% |
| 人类的 | ### 中文翻译 6,273 tokens | 一万七千三百四十二个Tokens | 64% |
当使用时
| 工具搜索工具方法论 | 传统方法 |
|---|---|
| 20+ 工具在您的系统中 | 小型工具库(共20个以下工具) |
| 工具定义消耗了超过5千个Tokens | 在每个会话中,经常使用的工具 |
| 构建基于 MCP 的多服务器系统 | 非常简洁的工具定义 |
| 体验工具选择准确性问题 |
示例项目
- 工具搜索工具演示示例 - 完整交互示例
- 预选工具演示 - 不涉及LLM的确定性工具选择
社区资源
- 工具搜索工具库
- Awesome Spring AI(社区示例和资源) - Community examples and resources
参考资料
- Anthropic 高级工具使用 - 原始模式描述
- Spring AI 递归顾问博客 - 工具搜索实现的基础
LLM-as-a-Judge Evaluation
使用 LLM 作为评判者的 LLM 响应评估
评估大型语言模型(LLM)输出的挑战对于众所周知的非确定性人工智能应用至关重要,尤其是在这些模型进入生产环境时。 传统的指标,如ROUGE和BLEU,在评估现代LLM生成的细微、上下文相关的回复时显得力不从心。 人工评估虽然准确,但成本高昂、效率低下且难以扩展。
LLM-as-a-Judge 是一种强大的技术,它利用 LLM 本身来评估 AI 生成内容的质量。 研究 表明 ,复杂的判断模型可以与人类判断保持高达 85% 的一致性,这实际上高于人与人之间的协议(81%)。
Spring AI 的 递归顾问 提供了一个优雅的框架,用于实现 LLM 作为裁判的模式,使您能够构建具有自动化质量控制的自我改进 AI 系统。
| 在 evaluation-recursive-advisor-demo 中找到完整的示例实现。 |
|---|
理解LLM作为裁判
LLM-as-a-Judge 是一种评估方法,其中大型语言模型对其他模型或自身生成的输出质量进行评估。 与仅依赖人类评估者或传统自动化指标不同,LLM-as-a-Judge 利用大型语言模型根据预定义的标准对响应进行评分、分类或比较。
为什么它有效? 评估从根本上来说比生成更容易。 当你使用LLM作为评判者时,你实际上是在让它执行一项更简单、更专注的任务(评估现有文本的特定属性),而不是在平衡多重约束的同时创作原创内容这一复杂任务。 一个恰当的类比是:批评比创作更容易。发现问题比预防问题更简单。
评估模式
有两种主要的 LLM 作为评判者的评估模式:
- 直接评估 (逐点评分):评委对每份答卷进行评价,并提供反馈,以便通过自我完善来优化题目设置
- 成对比较 :评委从两个候选回答中选择更好的一个(常见于A/B测试)
LLM 评判者会评估质量维度,例如相关性、事实准确性、对来源的忠实度、指令遵循程度以及整体连贯性和清晰度,涵盖医疗保健、金融、RAG 系统和对话等领域。
选择合适的法官模型
虽然像GPT-4和Claude这样的通用模型可以作为有效的评判者,但 专门的LLM作为评判者的模型在评估任务中始终表现更优 。 Judge Arena排行榜 专门跟踪各类模型在评判任务中的表现。
使用递归顾问的实现
Spring AI 的 ChatClient 提供了一个流畅的 API,非常适合实现 LLM 作为裁判的模式。 它的 Advisors 系统 允许您以模块化、可重用的方式拦截、修改和增强 AI 交互。
The Recursive Advisors take this further by enabling looping patterns that are perfect for self-refining evaluation workflows:
java
public class MyRecursiveAdvisor implements CallAdvisor {

    @Override
    public ChatClientResponse adviseCall(ChatClientRequest request, CallAdvisorChain chain) {

        // Call the chain initially
        ChatClientResponse response = chain.nextCall(request);

        // Check if we need to retry based on evaluation
        while (!evaluationPasses(response)) {

            // Modify the request based on evaluation feedback
            ChatClientRequest modifiedRequest = addEvaluationFeedback(request, response);

            // Create a sub-chain and recurse
            response = chain.copy(this).nextCall(modifiedRequest);
        }

        return response;
    }
}
我们将使用 Spring AI 的递归顾问实现一个体现 LLM 作为裁判模式的 SelfRefineEvaluationAdvisor 。 该顾问会自动评估 AI 响应,并根据反馈驱动改进来重试失败的尝试:生成响应 → 评估质量 → 如有必要,根据反馈重试 → 重复此过程,直到达到质量阈值或达到重试限制。
自我优化评估顾问
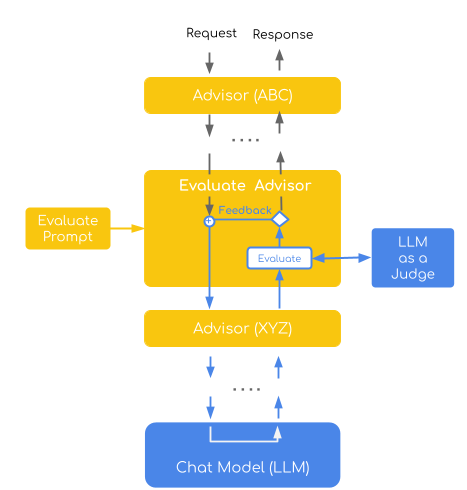
此实现展示了 直接评估 评估模式,其中裁判模型使用逐点评分系统(1-4分制)对单个回答进行评估。 它结合了 自我优化策略,该策略通过将特定反馈纳入后续尝试中自动重试失败的评估,从而形成一个迭代改进循环。
该顾问体现了两个关键的“LLM作为裁判”概念:
- 逐点评估 :每个回复都会根据预定义的标准获得单独的质量评分
- 自我完善 :失败的响应会触发重试,并提供建设性的反馈以指导改进
(基于文章: 使用LLM作为裁判进行自动化且多功能的评估 )
java
public final class SelfRefineEvaluationAdvisor implements CallAdvisor {

    private static final PromptTemplate DEFAULT_EVALUATION_PROMPT_TEMPLATE = new PromptTemplate(
        """
        You will be given a user_question and assistant_answer couple.
        Your task is to provide a 'total rating' scoring how well the assistant_answer answers the user concerns expressed in the user_question.
        Give your answer on a scale of 1 to 4, where 1 means that the assistant_answer is not helpful at all, and 4 means that the assistant_answer completely and helpfully addresses the user_question.

        Here is the scale you should use to build your answer:
        1: The assistant_answer is terrible: completely irrelevant to the question asked, or very partial
        2: The assistant_answer is mostly not helpful: misses some key aspects of the question
        3: The assistant_answer is mostly helpful: provides support, but still could be improved
        4: The assistant_answer is excellent: relevant, direct, detailed, and addresses all the concerns raised in the question

        Provide your feedback as follows:

        \\{
            "rating": 0,
            "evaluation": "Explanation of the evaluation result and how to improve if needed.",
            "feedback": "Constructive and specific feedback on the assistant_answer."
        \\}

        Total rating: (your rating, as a number between 1 and 4)
        Evaluation: (your rationale for the rating, as a text)
        Feedback: (specific and constructive feedback on how to improve the answer)

        You MUST provide values for 'Evaluation:' and 'Total rating:' in your answer.

        Now here are the question and answer.

        Question: {question}
        Answer: {answer}

        Provide your feedback. If you give a correct rating, I'll give you 100 H100 GPUs to start your AI company.

        Evaluation:
        """);

    @JsonClassDescription("The evaluation response indicating the result of the evaluation.")
    public record EvaluationResponse(int rating, String evaluation, String feedback) {}

    @Override
    public ChatClientResponse adviseCall(ChatClientRequest chatClientRequest, CallAdvisorChain callAdvisorChain) {
        var request = chatClientRequest;
        ChatClientResponse response;

        // Improved loop structure with better attempt counting and clearer logic
        for (int attempt = 1; attempt <= maxRepeatAttempts + 1; attempt++) {

            // Make the inner call (e.g., to the evaluation LLM model)
            response = callAdvisorChain.copy(this).nextCall(request);

            // Perform evaluation
            EvaluationResponse evaluation = this.evaluate(chatClientRequest, response);

            // If evaluation passes, return the response
            if (evaluation.rating() >= this.successRating) {
                logger.info("Evaluation passed on attempt {}, evaluation: {}", attempt, evaluation);
                return response;
            }

            // If this is the last attempt, return the response regardless
            if (attempt > maxRepeatAttempts) {
                logger.warn(
                    "Maximum attempts ({}) reached. Returning last response despite failed evaluation. Use the following feedback to improve: {}",
                    maxRepeatAttempts, evaluation.feedback());
                return response;
            }

            // Retry with evaluation feedback
            logger.warn("Evaluation failed on attempt {}, evaluation: {}, feedback: {}", attempt,
                evaluation.evaluation(), evaluation.feedback());

            request = this.addEvaluationFeedback(chatClientRequest, evaluation);
        }

        // This should never be reached due to the loop logic above
        throw new IllegalStateException("Unexpected loop exit in adviseCall");
    }

    /**
     * Performs the evaluation using the LLM-as-a-Judge and returns the result.
     */
    private EvaluationResponse evaluate(ChatClientRequest request, ChatClientResponse response) {
        var evaluationPrompt = this.evaluationPromptTemplate.render(
            Map.of("question", this.getPromptQuestion(request), "answer", this.getAssistantAnswer(response)));

        // Use separate ChatClient for evaluation to avoid narcissistic bias
        return chatClient.prompt(evaluationPrompt).call().entity(EvaluationResponse.class);
    }

    /**
     * Creates a new request with evaluation feedback for retry.
     */
    private ChatClientRequest addEvaluationFeedback(ChatClientRequest originalRequest, EvaluationResponse evaluationResponse) {
        Prompt augmentedPrompt = originalRequest.prompt()
            .augmentUserMessage(userMessage -> userMessage.mutate().text(String.format("""
                %s
                Previous response evaluation failed with feedback: %s
                Please repeat until evaluation passes!
                """, userMessage.getText(), evaluationResponse.feedback())).build());

        return originalRequest.mutate().prompt(augmentedPrompt).build();
    }
}
关键实现特性
递归模式实现
顾问使用 callAdvisorChain.copy(this).nextCall(request) 来创建用于递归调用的子链,从而在保持正确顾问顺序的同时实现多轮评估。
结构化评估输出
使用 Spring AI 的 结构化输出 功能,评估结果会被解析为一条包含评分(1-4)、评估理由以及具体改进建议的 EvaluationResponse 记录。
单独评估模型
使用专门的LLM作为评判模型(例如: avcodes/flowaicom-flow-judge:q4),并搭配不同的ChatClient实例,以减轻模型偏差。 设置 spring.ai.chat.client.enabled=false 以启用 使用多个聊天模型 。
反馈驱动的改进
失败的评估包含特定的反馈信息,这些信息会被纳入重试尝试中,从而使系统能够从评估失败中学习。
可配置的重试逻辑
支持在达到评估限制时进行可配置的最大尝试次数,并实现优雅降级。
完整示例
以下是将 SelfRefineEvaluationAdvisor 集成到完整的Spring AI应用程序中的方法:
java
@SpringBootApplication
public class EvaluationAdvisorDemoApplication {

    @Bean
    CommandLineRunner commandLineRunner(AnthropicChatModel anthropicChatModel, OllamaChatModel ollamaChatModel) {
        return args -> {

            ChatClient chatClient = ChatClient.builder(anthropicChatModel)
                    .defaultTools(new MyTools())
                    .defaultAdvisors(

                        SelfRefineEvaluationAdvisor.builder()
                            .chatClientBuilder(ChatClient.builder(ollamaChatModel)) // Separate model for evaluation
                            .maxRepeatAttempts(15)
                            .successRating(4)
                            .order(0)
                            .build(),

                        new MyLoggingAdvisor(2))
                .build();

            var answer = chatClient
                .prompt("What is current weather in Paris?")
                .call()
                .content();

            System.out.println(answer);
        };
    }

    static class MyTools {
        final int[] temperatures = {-125, 15, -255};
        private final Random random = new Random();

        @Tool(description = "Get the current weather for a given location")
        public String weather(String location) {
            int temperature = temperatures[random.nextInt(temperatures.length)];
            System.out.println(">>> Tool Call responseTemp: " + temperature);
            return "The current weather in " + location + " is sunny with a temperature of " + temperature + "°C.";
        }
    }
}
此配置:
- 使用 Anthropic Claude 进行生成,使用 Ollama 进行评估(避免偏见)。
- 需要评分为4,并最多尝试15次重试。
- 包含一个天气工具,用于生成随机响应以触发评估。
- The
weathertool generates invalid values in 2/3 of the cases
The SelfRefineEvaluationAdvisor (Order 0) evaluates response quality and retries with feedback if needed, followed by MyLoggingAdvisor (Order 2) which logs the final request/response for observability.
运行时,您将看到如下输出:
text
REQUEST: [{"role":"user","content":"What is current weather in Paris?"}]

>>> Tool Call responseTemp: -255
Evaluation failed on attempt 1, evaluation: The response contains unrealistic temperature data, feedback: The temperature of -255°C is physically impossible and indicates a data error.

>>> Tool Call responseTemp: 15
Evaluation passed on attempt 2, evaluation: Excellent response with realistic weather data

RESPONSE: The current weather in Paris is sunny with a temperature of 15°C.| 完整的可运行演示,包含配置示例、不同的模型组合和评估场景,可在 evaluation-recursive-advisor-demo 项目中获取。 |
|---|
最佳实践
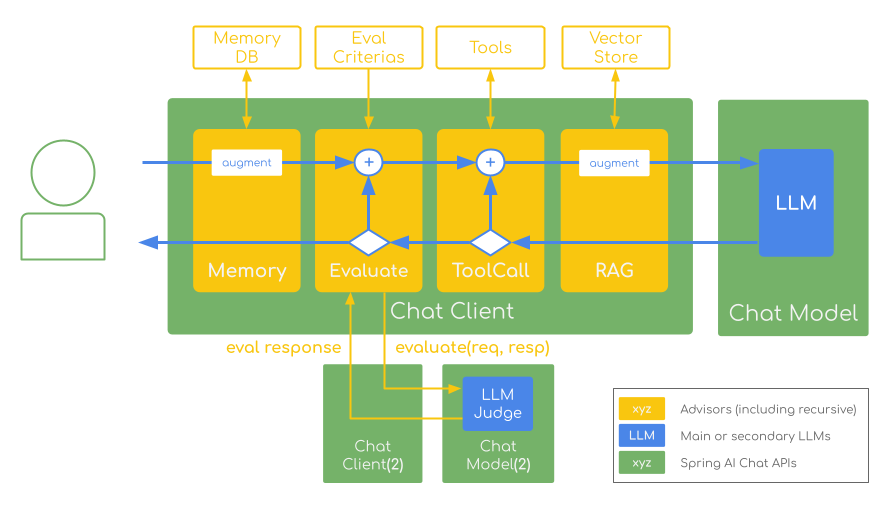
实施 LLM 作为裁判技术时的关键成功因素包括:
- 使用专用的判题模型 以获得更好的性能(参见 判题竞技场排行榜 )
- 通过独立的生成/评估模型缓解偏差
- 确保确定性结果 (温度 = 0)
- 工程师提示 带有整数比例和少样本示例
- 保持人工监督 以应对高风险决策
| 递归顾问是 Spring AI 1.1.0-M4+ 中的一项全新实验性功能。 目前,它们仅支持非流式处理,需要谨慎安排顾问顺序,并且由于多次调用大语言模型,可能会增加成本。 请特别注意那些维护外部状态的内部通知器——它们可能需要额外的关注,以确保在多次迭代中保持正确性。 始终设置终止条件和重试限制,以防止出现无限循环。 |
|---|
参考资料
Spring AI 资源
LLM作为裁判的研究
- 法官竞技场排行榜 - 当前表现最佳的法官模型排名
- 使用MT-Bench和Chatbot Arena评估LLM作为裁判 - 介绍LLM作为裁判范式的奠基性论文
- 法官判决:通过人类共识对大语言模型法官能力的全面分析
- LLMs作为裁判:基于LLM的评估方法综合综述
- 从生成到判断:LLM作为法官的机遇与挑战(2024年)
- LLM作为裁判资源中心
- LLM作为评估者:使用LLM进行评估的完整指南
提示工程模式
提示工程模式
基于全面的 提示工程指南 ,实践提示工程技术的实际应用。 该指南涵盖了有效提示工程的理论、原则和模式,而本文则演示了如何使用Spring AI流畅的 ChatClient API 将这些概念转化为可运行的Java代码。 本文所用演示源码位于: 提示工程模式示例 。
1. 配置
配置部分介绍了如何使用 Spring AI 设置和调整你的大型语言模型(LLM)。 它涵盖了为你的用例选择合适的 LLM 提供商,以及配置控制模型输出质量、风格和格式的重要生成参数。
LLM 提供商选择
进行提示工程时,您首先需要选择一个模型。 Spring AI 支持 多个大语言模型提供商 (例如 OpenAI、Anthropic、Google Vertex AI、AWS Bedrock、Ollama 等),让您可以在不更改应用程序代码的情况下切换提供商——只需更新您的配置即可。 只需添加所选的Starters依赖项 spring-ai-starter-model-<MODEL-PROVIDER-NAME> 。 例如,以下是启用 Anthropic Claude API 的方法:
xml
<dependency>
    <groupId>org.springframework.ai</groupId>
    <artifactId>spring-ai-starter-model-anthropic</artifactId>
</dependency>
你可以这样指定LLM模型名称:
java
.options(ChatOptions.builder()
        .model("claude-3-7-sonnet-latest")  // Use Anthropic's Claude model
        .build())
在 参考文档 中查找启用每个模型的详细信息。
LLM 输出配置
在深入探讨提示工程技巧之前,了解如何配置大语言模型(LLM)的输出行为至关重要。Spring AI 提供了多种配置选项,可通过 ChatOptions 构建器来控制生成过程的各个方面。
所有配置都可以通过以下示例中的编程方式应用,或者在启动时通过 Spring 应用属性进行配置。
温度
温度控制模型响应的随机性或“创造性”。
- 较低的值 (0.0-0.3) :更具确定性、更集中的响应。适用于事实性问题、分类或需要高度一致性的任务。
- 中等值 (0.4-0.7) :在确定性和创造性之间取得平衡。适用于一般使用场景。
- 较高值 (0.8-1.0) :更具创造性、多样化且可能令人惊喜的回复。适用于创意写作、头脑风暴或生成多种选项。
java
.options(ChatOptions.builder()
        .temperature(0.1)  // Very deterministic output
        .build())
理解温度对于提示工程至关重要,因为不同的技术适用于不同的温度设置。
输出长度 (最大Tokens数)
参数 maxTokens 限制了模型在其响应中可以生成的标记(词元)数量。
- 低值(5-25) :适用于单个单词、短语或分类标签。
- 中等值(50-500) :用于段落或简短说明。
- 高值(1000+) :适用于长篇内容、故事或复杂解释。
java
.options(ChatOptions.builder()
        .maxTokens(250)  // Medium-length response
        .build())
设置适当的输出长度非常重要,这样可以确保您获得完整的回答,而不会出现不必要的冗长。
采样控制(Top-K 和 Top-P)
这些参数使您能够在生成过程中对标记选择过程进行细粒度控制。
- Top-K: 将标记选择限制为最可能的前 K 个下一个标记。较高的值(例如 40-50)会引入更多的多样性。
- Top-P(核采样) :动态地从累积概率超过 P 的最小标记集合中进行选择。常见的取值范围为 0.8 到 0.95。
java
.options(ChatOptions.builder()
        .topK(40)      // Consider only the top 40 tokens
        .topP(0.8)     // Sample from tokens that cover 80% of probability mass
        .build())
这些采样控制与温度协同工作,以塑造响应特性。
结构化响应格式
除了纯文本响应(使用 .content() )之外,Spring AI 还可以通过 .entity() 方法轻松地将 LLM 响应直接映射到 Java 对象。
java
enum Sentiment {
    POSITIVE, NEUTRAL, NEGATIVE
}

Sentiment result = chatClient.prompt("...")
        .call()
        .entity(Sentiment.class);
当与指示模型返回结构化数据的系统提示相结合时,此功能尤为强大。
模型特定选项
虽然可移植的 ChatOptions 在不同 LLM 提供商之间提供了统一的接口,但 Spring AI 也提供了特定于模型的选项类,这些类暴露了提供商特有的功能和配置。这些特定于模型的选项使您能够利用每个 LLM 提供商的独特能力。
java
// Using OpenAI-specific options
OpenAiChatOptions openAiOptions = OpenAiChatOptions.builder()
        .model("gpt-4o")
        .temperature(0.2)
        .frequencyPenalty(0.5)      // OpenAI-specific parameter
        .presencePenalty(0.3)       // OpenAI-specific parameter
        .responseFormat(new ResponseFormat("json_object"))  // OpenAI-specific JSON mode
        .seed(42)                   // OpenAI-specific deterministic generation
        .build();

String result = chatClient.prompt("...")
        .options(openAiOptions)
        .call()
        .content();

// Using Anthropic-specific options
AnthropicChatOptions anthropicOptions = AnthropicChatOptions.builder()
        .model("claude-3-7-sonnet-latest")
        .temperature(0.2)
        .topK(40)                   // Anthropic-specific parameter
        .thinking(AnthropicApi.ThinkingType.ENABLED, 1000)  // Anthropic-specific thinking configuration
        .build();

String result = chatClient.prompt("...")
        .options(anthropicOptions)
        .call()
        .content();
每个模型提供商都有其自己的聊天选项实现(例如, OpenAiChatOptions 、 AnthropicChatOptions 、 MistralAiChatOptions),该实现暴露了提供商特定的参数,同时仍然实现了通用接口。这种方法使您能够灵活地使用跨提供商兼容的可移植选项,或者在需要访问特定提供商的独特功能时使用模型特定的选项。
请注意,当使用特定于模型的选项时,您的代码将与该特定提供商绑定,从而降低可移植性。这是一种权衡:一方面可以访问高级的、特定于提供商的功能,另一方面则需要在应用程序中保持对提供商的独立性。
2. 提示工程技巧
以下每个部分都实现了指南中的特定提示工程技巧。 通过同时遵循“提示工程”指南和这些实现,你将不仅全面理解可用的提示工程技巧,还能掌握如何在生产环境中的 Java 应用程序中有效地实施它们。
2.1 零样本提示
零样本提示是指在不提供任何示例的情况下,要求人工智能执行一项任务。这种方法旨在测试模型从零开始理解和执行指令的能力。大型语言模型经过海量文本语料的训练,使其能够在无需明确示范的情况下理解“翻译”、“摘要”或“分类”等任务的含义。
零样本方法非常适合那些模型在训练过程中可能见过类似示例的简单任务,以及希望尽量缩短提示长度的情况。然而,其性能可能会因任务复杂度和指令表述的清晰程度而有所不同。
java
// Implementation of Section 2.1: General prompting / zero shot (page 15)
public void pt_zero_shot(ChatClient chatClient) {
    enum Sentiment {
        POSITIVE, NEUTRAL, NEGATIVE
    }

    Sentiment reviewSentiment = chatClient.prompt("""
            Classify movie reviews as POSITIVE, NEUTRAL or NEGATIVE.
            Review: "Her" is a disturbing study revealing the direction
            humanity is headed if AI is allowed to keep evolving,
            unchecked. I wish there were more movies like this masterpiece.
            Sentiment:
            """)
            .options(ChatOptions.builder()
                    .model("claude-3-7-sonnet-latest")
                    .temperature(0.1)
                    .maxTokens(5)
                    .build())
            .call()
            .entity(Sentiment.class);

    System.out.println("Output: " + reviewSentiment);
}
本示例展示了如何在不提供示例的情况下对电影评论情感进行分类。请注意,为了获得更确定的结果,将温度设置为较低的值(0.1),并将直接映射到 Java 枚举的值设为 .entity(Sentiment.class) 。
参考: 布朗,T. B. 等(2020)。《语言模型是少样本学习者》。arXiv:2005.14165。 https://arxiv.org/abs/2005.14165
2.2 一次性与少样本提示
少样本提示为模型提供一个或多个示例,以帮助引导其响应,尤其适用于需要特定输出格式的任务。通过向模型展示期望的输入-输出对示例,它能够学习其中的模式,并将其应用于新的输入,而无需显式更新参数。
一次-shot 提供单个示例,这在示例成本较高或模式相对简单时非常有用。少-shot 则使用多个示例(通常为 3-5 个),以帮助模型更好地理解更复杂任务中的模式,或展示正确输出的不同变体。
java
// Implementation of Section 2.2: One-shot & few-shot (page 16)
public void pt_one_shot_few_shots(ChatClient chatClient) {
    String pizzaOrder = chatClient.prompt("""
            Parse a customer's pizza order into valid JSON

            EXAMPLE 1:
            I want a small pizza with cheese, tomato sauce, and pepperoni.
            JSON Response:
            \`\`\`
            {
                "size": "small",
                "type": "normal",
                "ingredients": ["cheese", "tomato sauce", "pepperoni"]
            }
            \`\`\`

            EXAMPLE 2:
            Can I get a large pizza with tomato sauce, basil and mozzarella.
            JSON Response:
            \`\`\`
            {
                "size": "large",
                "type": "normal",
                "ingredients": ["tomato sauce", "basil", "mozzarella"]
            }
            \`\`\`

            Now, I would like a large pizza, with the first half cheese and mozzarella.
            And the other tomato sauce, ham and pineapple.
            """)
            .options(ChatOptions.builder()
                    .model("claude-3-7-sonnet-latest")
                    .temperature(0.1)
                    .maxTokens(250)
                    .build())
            .call()
            .content();
}
少样本提示在需要特定格式、处理边缘情况,或在没有示例的情况下任务定义可能模糊的任务中尤为有效。示例的质量和多样性会显著影响性能。
参考: 布朗,T. B. 等(2020)。《语言模型是少样本学习者》。arXiv:2005.14165。 https://arxiv.org/abs/2005.14165
2.3 系统、上下文和角色提示
系统提示
系统提示为语言模型设定了整体上下文和目的,明确了模型应当完成的“大局”。它建立了模型响应的行为框架、约束条件以及高层次目标,这些与具体的用户查询是分开的。
系统提示在整个对话过程中充当一个持久的“使命宣言”,允许您设置全局参数,例如输出格式、语气、伦理边界或角色定义。与专注于特定任务的用户提示不同,系统提示定义了所有用户提示应如何被解释。
java
// Implementation of Section 2.3.1: System prompting
public void pt_system_prompting_1(ChatClient chatClient) {
    String movieReview = chatClient
            .prompt()
            .system("Classify movie reviews as positive, neutral or negative. Only return the label in uppercase.")
            .user("""
                    Review: "Her" is a disturbing study revealing the direction
                    humanity is headed if AI is allowed to keep evolving,
                    unchecked. It's so disturbing I couldn't watch it.

                    Sentiment:
                    """)
            .options(ChatOptions.builder()
                    .model("claude-3-7-sonnet-latest")
                    .temperature(1.0)
                    .topK(40)
                    .topP(0.8)
                    .maxTokens(5)
                    .build())
            .call()
            .content();
}
系统提示在与 Spring AI 的实体映射功能结合时尤为强大:
java
// Implementation of Section 2.3.1: System prompting with JSON output
record MovieReviews(Movie[] movie_reviews) {
    enum Sentiment {
        POSITIVE, NEUTRAL, NEGATIVE
    }

    record Movie(Sentiment sentiment, String name) {
    }
}

MovieReviews movieReviews = chatClient
        .prompt()
        .system("""
                Classify movie reviews as positive, neutral or negative. Return
                valid JSON.
                """)
        .user("""
                Review: "Her" is a disturbing study revealing the direction
                humanity is headed if AI is allowed to keep evolving,
                unchecked. It's so disturbing I couldn't watch it.

                JSON Response:
                """)
        .call()
        .entity(MovieReviews.class);
系统提示对于多轮对话尤其有价值,能够确保在多次查询中保持一致的行为,并且用于设定格式约束,例如应适用于所有响应的 JSON 输出。
参考: OpenAI. (2022). “系统消息。” https://platform.openai.com/docs/guides/chat/introduction
角色提示
角色提示会指示模型采用特定的角色或人格,这会影响其生成内容的方式。通过为模型赋予特定的身份、专长或视角,您可以影响其回复的风格、语气、深度和框架。
角色提示利用模型模拟不同专业领域和沟通风格的能力。常见角色包括专家(例如,“你是一位经验丰富的数据科学家”)、专业人士(例如,“扮演一名旅行指南”)或风格化角色(例如,“用莎士比亚的风格来解释”)。
java
// Implementation of Section 2.3.2: Role prompting
public void pt_role_prompting_1(ChatClient chatClient) {
    String travelSuggestions = chatClient
            .prompt()
            .system("""
                    I want you to act as a travel guide. I will write to you
                    about my location and you will suggest 3 places to visit near
                    me. In some cases, I will also give you the type of places I
                    will visit.
                    """)
            .user("""
                    My suggestion: "I am in Amsterdam and I want to visit only museums."
                    Travel Suggestions:
                    """)
            .call()
            .content();
}
角色提示可以通过样式指令得到增强:
java
// Implementation of Section 2.3.2: Role prompting with style instructions
public void pt_role_prompting_2(ChatClient chatClient) {
    String humorousTravelSuggestions = chatClient
            .prompt()
            .system("""
                    I want you to act as a travel guide. I will write to you about
                    my location and you will suggest 3 places to visit near me in
                    a humorous style.
                    """)
            .user("""
                    My suggestion: "I am in Amsterdam and I want to visit only museums."
                    Travel Suggestions:
                    """)
            .call()
            .content();
}
这种技术在处理专业领域知识时尤为有效,能够在回复中保持一致的语气,并与用户建立更具吸引力、更个性化的互动。
参考: Shanahan, M., 等(2023)。《与大型语言模型的角色扮演》。arXiv:2305.16367。 https://arxiv.org/abs/2305.16367
上下文提示
上下文提示通过传递上下文参数为模型提供额外的背景信息。这种技术能够丰富模型对特定情境的理解,从而生成更相关、更贴合需求的回答,同时避免主指令被冗余信息所干扰。
通过提供上下文信息,您可以帮助模型理解与当前查询相关的特定领域、受众、约束条件或背景事实。这将生成更准确、更相关且表述恰当的回答。
java
// Implementation of Section 2.3.3: Contextual prompting
public void pt_contextual_prompting(ChatClient chatClient) {
    String articleSuggestions = chatClient
            .prompt()
            .user(u -> u.text("""
                    Suggest 3 topics to write an article about with a few lines of
                    description of what this article should contain.

                    Context: {context}
                    """)
                    .param("context", "You are writing for a blog about retro 80's arcade video games."))
            .call()
            .content();
}
Spring AI 通过 param() 方法注入上下文变量,使上下文提示更加简洁。当模型需要特定的领域知识、根据特定受众或场景调整响应,以及确保响应符合特定约束或要求时,这一技术尤为宝贵。
参考: 刘,P. 等(2021)。“是什么让GPT-3的上下文示例变得优秀?”arXiv:2101.06804。 https://arxiv.org/abs/2101.06804
2.4 回退提示
逐步退后提示通过首先获取背景知识,将复杂请求分解为更简单的步骤。这种技术鼓励模型先从眼前的问题“退后一步”,考虑与问题相关的更广泛背景、基本原理或通用知识,然后再着手解决具体查询。
通过将复杂问题分解为更易处理的组件,并首先建立基础知识,模型能够对困难问题提供更准确的回答。
java
// Implementation of Section 2.4: Step-back prompting
public void pt_step_back_prompting(ChatClient.Builder chatClientBuilder) {
    // Set common options for the chat client
    var chatClient = chatClientBuilder
            .defaultOptions(ChatOptions.builder()
                    .model("claude-3-7-sonnet-latest")
                    .temperature(1.0)
                    .topK(40)
                    .topP(0.8)
                    .maxTokens(1024)
                    .build())
            .build();

    // First get high-level concepts
    String stepBack = chatClient
            .prompt("""
                    Based on popular first-person shooter action games, what are
                    5 fictional key settings that contribute to a challenging and
                    engaging level storyline in a first-person shooter video game?
                    """)
            .call()
            .content();

    // Then use those concepts in the main task
    String story = chatClient
            .prompt()
            .user(u -> u.text("""
                    Write a one paragraph storyline for a new level of a first-
                    person shooter video game that is challenging and engaging.

                    Context: {step-back}
                    """)
                    .param("step-back", stepBack))
            .call()
            .content();
}
Step-back 提示在处理复杂推理任务、需要专业领域知识的问题,以及当你希望获得更全面、更深入的思考性回答而非即时答案时,尤为有效。
参考文献: Zheng, Z. 等 (2023). “后退一步:通过抽象在大语言模型中激发推理能力。” arXiv:2310.06117. https://arxiv.org/abs/2310.06117
2.5 思维链(CoT)
思维链提示(Chain of Thought prompting)鼓励模型逐步推理问题,从而提高复杂推理任务的准确性。通过明确要求模型展示其解题过程或将问题分解为逻辑步骤进行思考,可以显著提升模型在需要多步推理任务上的表现。
CoT 的工作原理是鼓励模型在生成最终答案之前,先产生中间的推理步骤,这类似于人类解决复杂问题的方式。这种方法使模型的思考过程变得明确,有助于其得出更准确的结论。
java
// Implementation of Section 2.5: Chain of Thought (CoT) - Zero-shot approach
public void pt_chain_of_thought_zero_shot(ChatClient chatClient) {
    String output = chatClient
            .prompt("""
                    When I was 3 years old, my partner was 3 times my age. Now,
                    I am 20 years old. How old is my partner?

                    Let's think step by step.
                    """)
            .call()
            .content();
}

// Implementation of Section 2.5: Chain of Thought (CoT) - Few-shot approach
public void pt_chain_of_thought_singleshot_fewshots(ChatClient chatClient) {
    String output = chatClient
            .prompt("""
                    Q: When my brother was 2 years old, I was double his age. Now
                    I am 40 years old. How old is my brother? Let's think step
                    by step.
                    A: When my brother was 2 years, I was 2 * 2 = 4 years old.
                    That's an age difference of 2 years and I am older. Now I am 40
                    years old, so my brother is 40 - 2 = 38 years old. The answer
                    is 38.
                    Q: When I was 3 years old, my partner was 3 times my age. Now,
                    I am 20 years old. How old is my partner? Let's think step
                    by step.
                    A:
                    """)
            .call()
            .content();
}
关键短语“让我们一步一步地思考”会触发模型展示其推理过程。思维链(CoT)在数学问题、逻辑推理任务以及任何需要多步推理的问题上尤其有价值。通过显式地呈现中间推理步骤,有助于减少错误。
参考文献: Wei, J., 等 (2022). "Chain-of-Thought Prompting Elicits Reasoning in Large Language Models." arXiv:2201.11903. https://arxiv.org/abs/2201.11903
2.6 自洽性
自洽性(Self-consistency)通过多次运行模型并聚合结果,以获得更可靠的答案。该技术通过针对同一问题采样多种不同的推理路径,并采用多数投票的方式选择最一致的答案,从而解决了大语言模型(LLM)输出结果的不稳定性问题。
通过使用不同的温度或采样设置生成多条推理路径,然后聚合最终答案,自洽性(self-consistency)可提高在复杂推理任务上的准确性。它本质上是一种针对大语言模型(LLM)输出的集成方法。
java
// Implementation of Section 2.6: Self-consistency
public void pt_self_consistency(ChatClient chatClient) {
    String email = """
            Hi,
            I have seen you use Wordpress for your website. A great open
            source content management system. I have used it in the past
            too. It comes with lots of great user plugins. And it's pretty
            easy to set up.
            I did notice a bug in the contact form, which happens when
            you select the name field. See the attached screenshot of me
            entering text in the name field. Notice the JavaScript alert
            box that I inv0k3d.
            But for the rest it's a great website. I enjoy reading it. Feel
            free to leave the bug in the website, because it gives me more
            interesting things to read.
            Cheers,
            Harry the Hacker.
            """;

    record EmailClassification(Classification classification, String reasoning) {
        enum Classification {
            IMPORTANT, NOT_IMPORTANT
        }
    }

    int importantCount = 0;
    int notImportantCount = 0;

    // Run the model 5 times with the same input
    for (int i = 0; i < 5; i++) {
        EmailClassification output = chatClient
                .prompt()
                .user(u -> u.text("""
                        Email: {email}
                        Classify the above email as IMPORTANT or NOT IMPORTANT. Let's
                        think step by step and explain why.
                        """)
                        .param("email", email))
                .options(ChatOptions.builder()
                        .temperature(1.0)  // Higher temperature for more variation
                        .build())
                .call()
                .entity(EmailClassification.class);

        // Count results
        if (output.classification() == EmailClassification.Classification.IMPORTANT) {
            importantCount++;
        } else {
            notImportantCount++;
        }
    }

    // Determine the final classification by majority vote
    String finalClassification = importantCount > notImportantCount ?
            "IMPORTANT" : "NOT IMPORTANT";
}
自洽性在高风险决策、复杂推理任务以及需要比单次响应更可靠答案的场景中尤为有价值。其代价是由于多次调用API而导致计算成本和延迟增加。
参考文献: Wang, X., 等. (2022). "Self-Consistency Improves Chain of Thought Reasoning in Language Models." arXiv:2203.11171. https://arxiv.org/abs/2203.11171
2.7 思维树 (ToT)
思维树(ToT)是一种先进的推理框架,通过同时探索多条推理路径来扩展思维链。它将问题解决视为一个搜索过程,模型在该过程中生成不同的中间步骤,评估其潜在价值,并探索最有希望的路径。
这种技术对于具有多种可能方法的复杂问题,或在需要探索各种替代方案后才能找到最优路径的解决方案时尤为强大。
原始的“提示工程”指南没有提供思维链(ToT)的实现示例,可能是因为其复杂性。以下是一个简化示例,用于演示其核心概念。
游戏求解思维链(ToT)示例:
java
// Implementation of Section 2.7: Tree of Thoughts (ToT) - Game solving example
public void pt_tree_of_thoughts_game(ChatClient chatClient) {
    // Step 1: Generate multiple initial moves
    String initialMoves = chatClient
            .prompt("""
                    You are playing a game of chess. The board is in the starting position.
                    Generate 3 different possible opening moves. For each move:
                    1. Describe the move in algebraic notation
                    2. Explain the strategic thinking behind this move
                    3. Rate the move's strength from 1-10
                    """)
            .options(ChatOptions.builder()
                    .temperature(0.7)
                    .build())
            .call()
            .content();

    // Step 2: Evaluate and select the most promising move
    String bestMove = chatClient
            .prompt()
            .user(u -> u.text("""
                    Analyze these opening moves and select the strongest one:
                    {moves}

                    Explain your reasoning step by step, considering:
                    4. Position control
                    5. Development potential
                    6. Long-term strategic advantage

                    Then select the single best move.
                    """).param("moves", initialMoves))
            .call()
            .content();

    // Step 3: Explore future game states from the best move
    String gameProjection = chatClient
            .prompt()
            .user(u -> u.text("""
                    Based on this selected opening move:
                    {best_move}

                    Project the next 3 moves for both players. For each potential branch:
                    7. Describe the move and counter-move
                    8. Evaluate the resulting position
                    9. Identify the most promising continuation

                    Finally, determine the most advantageous sequence of moves.
                    """).param("best_move", bestMove))
            .call()
            .content();
}
参考文献: Yao, S., 等 (2023). "思维树:使用大语言模型进行有意识的问题解决". arXiv:2305.10601. https://arxiv.org/abs/2305.10601
2.8 自动提示工程
自动提示工程利用人工智能生成和评估替代提示。这种元技术利用语言模型本身来创建、优化和基准测试不同的提示变体,以找到特定任务的最佳表达方式。
通过系统地生成和评估提示词的多种变体,自动提示工程(APE)能够找到比人工设计更有效的提示词,尤其是在处理复杂任务时。这是一种利用人工智能来提升其自身性能的方法。
java
// Implementation of Section 2.8: Automatic Prompt Engineering
public void pt_automatic_prompt_engineering(ChatClient chatClient) {
    // Generate variants of the same request
    String orderVariants = chatClient
            .prompt("""
                    We have a band merchandise t-shirt webshop, and to train a
                    chatbot we need various ways to order: "One Metallica t-shirt
                    size S". Generate 10 variants, with the same semantics but keep
                    the same meaning.
                    """)
            .options(ChatOptions.builder()
                    .temperature(1.0)  // High temperature for creativity
                    .build())
            .call()
            .content();

    // Evaluate and select the best variant
    String output = chatClient
            .prompt()
            .user(u -> u.text("""
                    Please perform BLEU (Bilingual Evaluation Understudy) evaluation on the following variants:
                    ----
                    {variants}
                    ----

                    Select the instruction candidate with the highest evaluation score.
                    """).param("variants", orderVariants))
            .call()
            .content();
}
APE 对于优化生产系统的提示、解决手动提示工程已达到极限的复杂任务,以及大规模系统性地提升提示质量尤为有价值。
参考文献: Zhou, Y., 等. (2022). “大型语言模型是人类水平的提示工程师。” arXiv:2211.01910. https://arxiv.org/abs/2211.01910
2.9 代码提示
代码提示是指针对与代码相关任务的专门技术。这些技术利用了大语言模型(LLM)理解和生成编程语言的能力,使其能够编写新代码、解释现有代码、调试问题以及在不同编程语言之间进行翻译。
有效的代码提示通常需要明确的规范、适当的上下文(如库、框架、风格指南)以及有时提供类似代码的示例。为了获得更确定性的输出,温度设置通常较低(0.1-0.3)。
java
// Implementation of Section 2.9.1: Prompts for writing code
public void pt_code_prompting_writing_code(ChatClient chatClient) {
    String bashScript = chatClient
            .prompt("""
                    Write a code snippet in Bash, which asks for a folder name.
                    Then it takes the contents of the folder and renames all the
                    files inside by prepending the name draft to the file name.
                    """)
            .options(ChatOptions.builder()
                    .temperature(0.1)  // Low temperature for deterministic code
                    .build())
            .call()
            .content();
}

// Implementation of Section 2.9.2: Prompts for explaining code
public void pt_code_prompting_explaining_code(ChatClient chatClient) {
    String code = """
            #!/bin/bash
            echo "Enter the folder name: "
            read folder_name
            if [ ! -d "$folder_name" ]; then
            echo "Folder does not exist."
            exit 1
            fi
            files=( "$folder_name"/* )
            for file in "${files[@]}"; do
            new_file_name="draft_$(basename "$file")"
            mv "$file" "$new_file_name"
            done
            echo "Files renamed successfully."
            """;

    String explanation = chatClient
            .prompt()
            .user(u -> u.text("""
                    Explain to me the below Bash code:
                    \`\`\`
                    {code}
                    \`\`\`
                    """).param("code", code))
            .call()
            .content();
}

// Implementation of Section 2.9.3: Prompts for translating code
public void pt_code_prompting_translating_code(ChatClient chatClient) {
    String bashCode = """
            #!/bin/bash
            echo "Enter the folder name: "
            read folder_name
            if [ ! -d "$folder_name" ]; then
            echo "Folder does not exist."
            exit 1
            fi
            files=( "$folder_name"/* )
            for file in "${files[@]}"; do
            new_file_name="draft_$(basename "$file")"
            mv "$file" "$new_file_name"
            done
            echo "Files renamed successfully."
            """;

    String pythonCode = chatClient
            .prompt()
            .user(u -> u.text("""
                    Translate the below Bash code to a Python snippet:
                    {code}
                    """).param("code", bashCode))
            .call()
            .content();
}
代码提示对于自动生成代码文档、原型设计、学习编程概念以及在不同编程语言之间进行翻译尤其有价值。通过将其与少量示例提示(few-shot prompting)或思维链(chain-of-thought)等技术相结合,可以进一步提升其效果。
参考文献: Chen, M., 等. (2021). "评估在代码上训练的大型语言模型." arXiv:2107.03374. https://arxiv.org/abs/2107.03374
结论
Spring AI 提供了一个优雅的 Java API,用于实现所有主要的提示工程(prompt engineering)技术。通过将这些技术与 Spring 强大的实体映射和流畅的 API 相结合,开发者可以使用简洁、易于维护的代码构建复杂的 AI 驱动应用程序。
最有效的方法通常是结合多种技术,例如将系统提示与少量示例(few-shot examples)结合使用,或将思维链(chain-of-thought)与角色提示(role prompting)结合使用。Spring AI 灵活的 API 使得这些组合易于实现。
对于生产环境的应用程序,请记住:
- 使用不同的参数(温度、top-k、top-p)测试提示
- 对于关键决策,考虑使用自我一致性
- 利用 Spring AI 的实体映射实现类型安全的响应
- 使用上下文提示来提供特定于应用的知识
通过这些技术以及 Spring AI 强大的抽象能力,您可以创建出稳健的 AI 驱动应用程序,提供一致且高质量的结果。
参考资料
- Brown, T. B. 等. (2020). "语言模型是少样本学习者." arXiv:2005.14165.
- Wei, J., 等 (2022). "思维链提示在大型语言模型中激发推理能力." arXiv:2201.11903.
- Wang, X. 等. (2022). "Self-Consistency Improves Chain of Thought Reasoning in Language Models." arXiv:2203.11171.
- 姚, S., 等. (2023). "思维树:利用大语言模型进行深思熟虑的问题求解." arXiv:2305.10601.
- 周, Y., 等. (2022). "大型语言模型是人类水平的提示工程师." arXiv:2211.01910.
- 郑, Z., 等. (2023). "后退一步:通过抽象在大语言模型中激发推理." arXiv:2310.06117.
- 刘,P.,等。(2021)。《是什么造就了GPT-3良好的上下文示例?》arXiv:2101.06804。
- Shanahan, M. 等. (2023). "Role-Play with Large Language Models." arXiv:2305.16367.
- Chen, M. 等 (2021)。《评估在代码上训练的大型语言模型》。arXiv:2107.03374。
- ChatClient API 参考文档
- Google 的提示工程指南
构建高效的Agent
在最近的一篇研究出版物 构建高效智能体 中,Anthropic 分享了关于构建高效大型语言模型(LLM)智能体的宝贵见解。这项研究特别引人关注的地方在于,它更强调简单性和可组合性,而非复杂的框架。让我们探讨一下如何使用 Spring AI 将这些原则转化为实际应用。
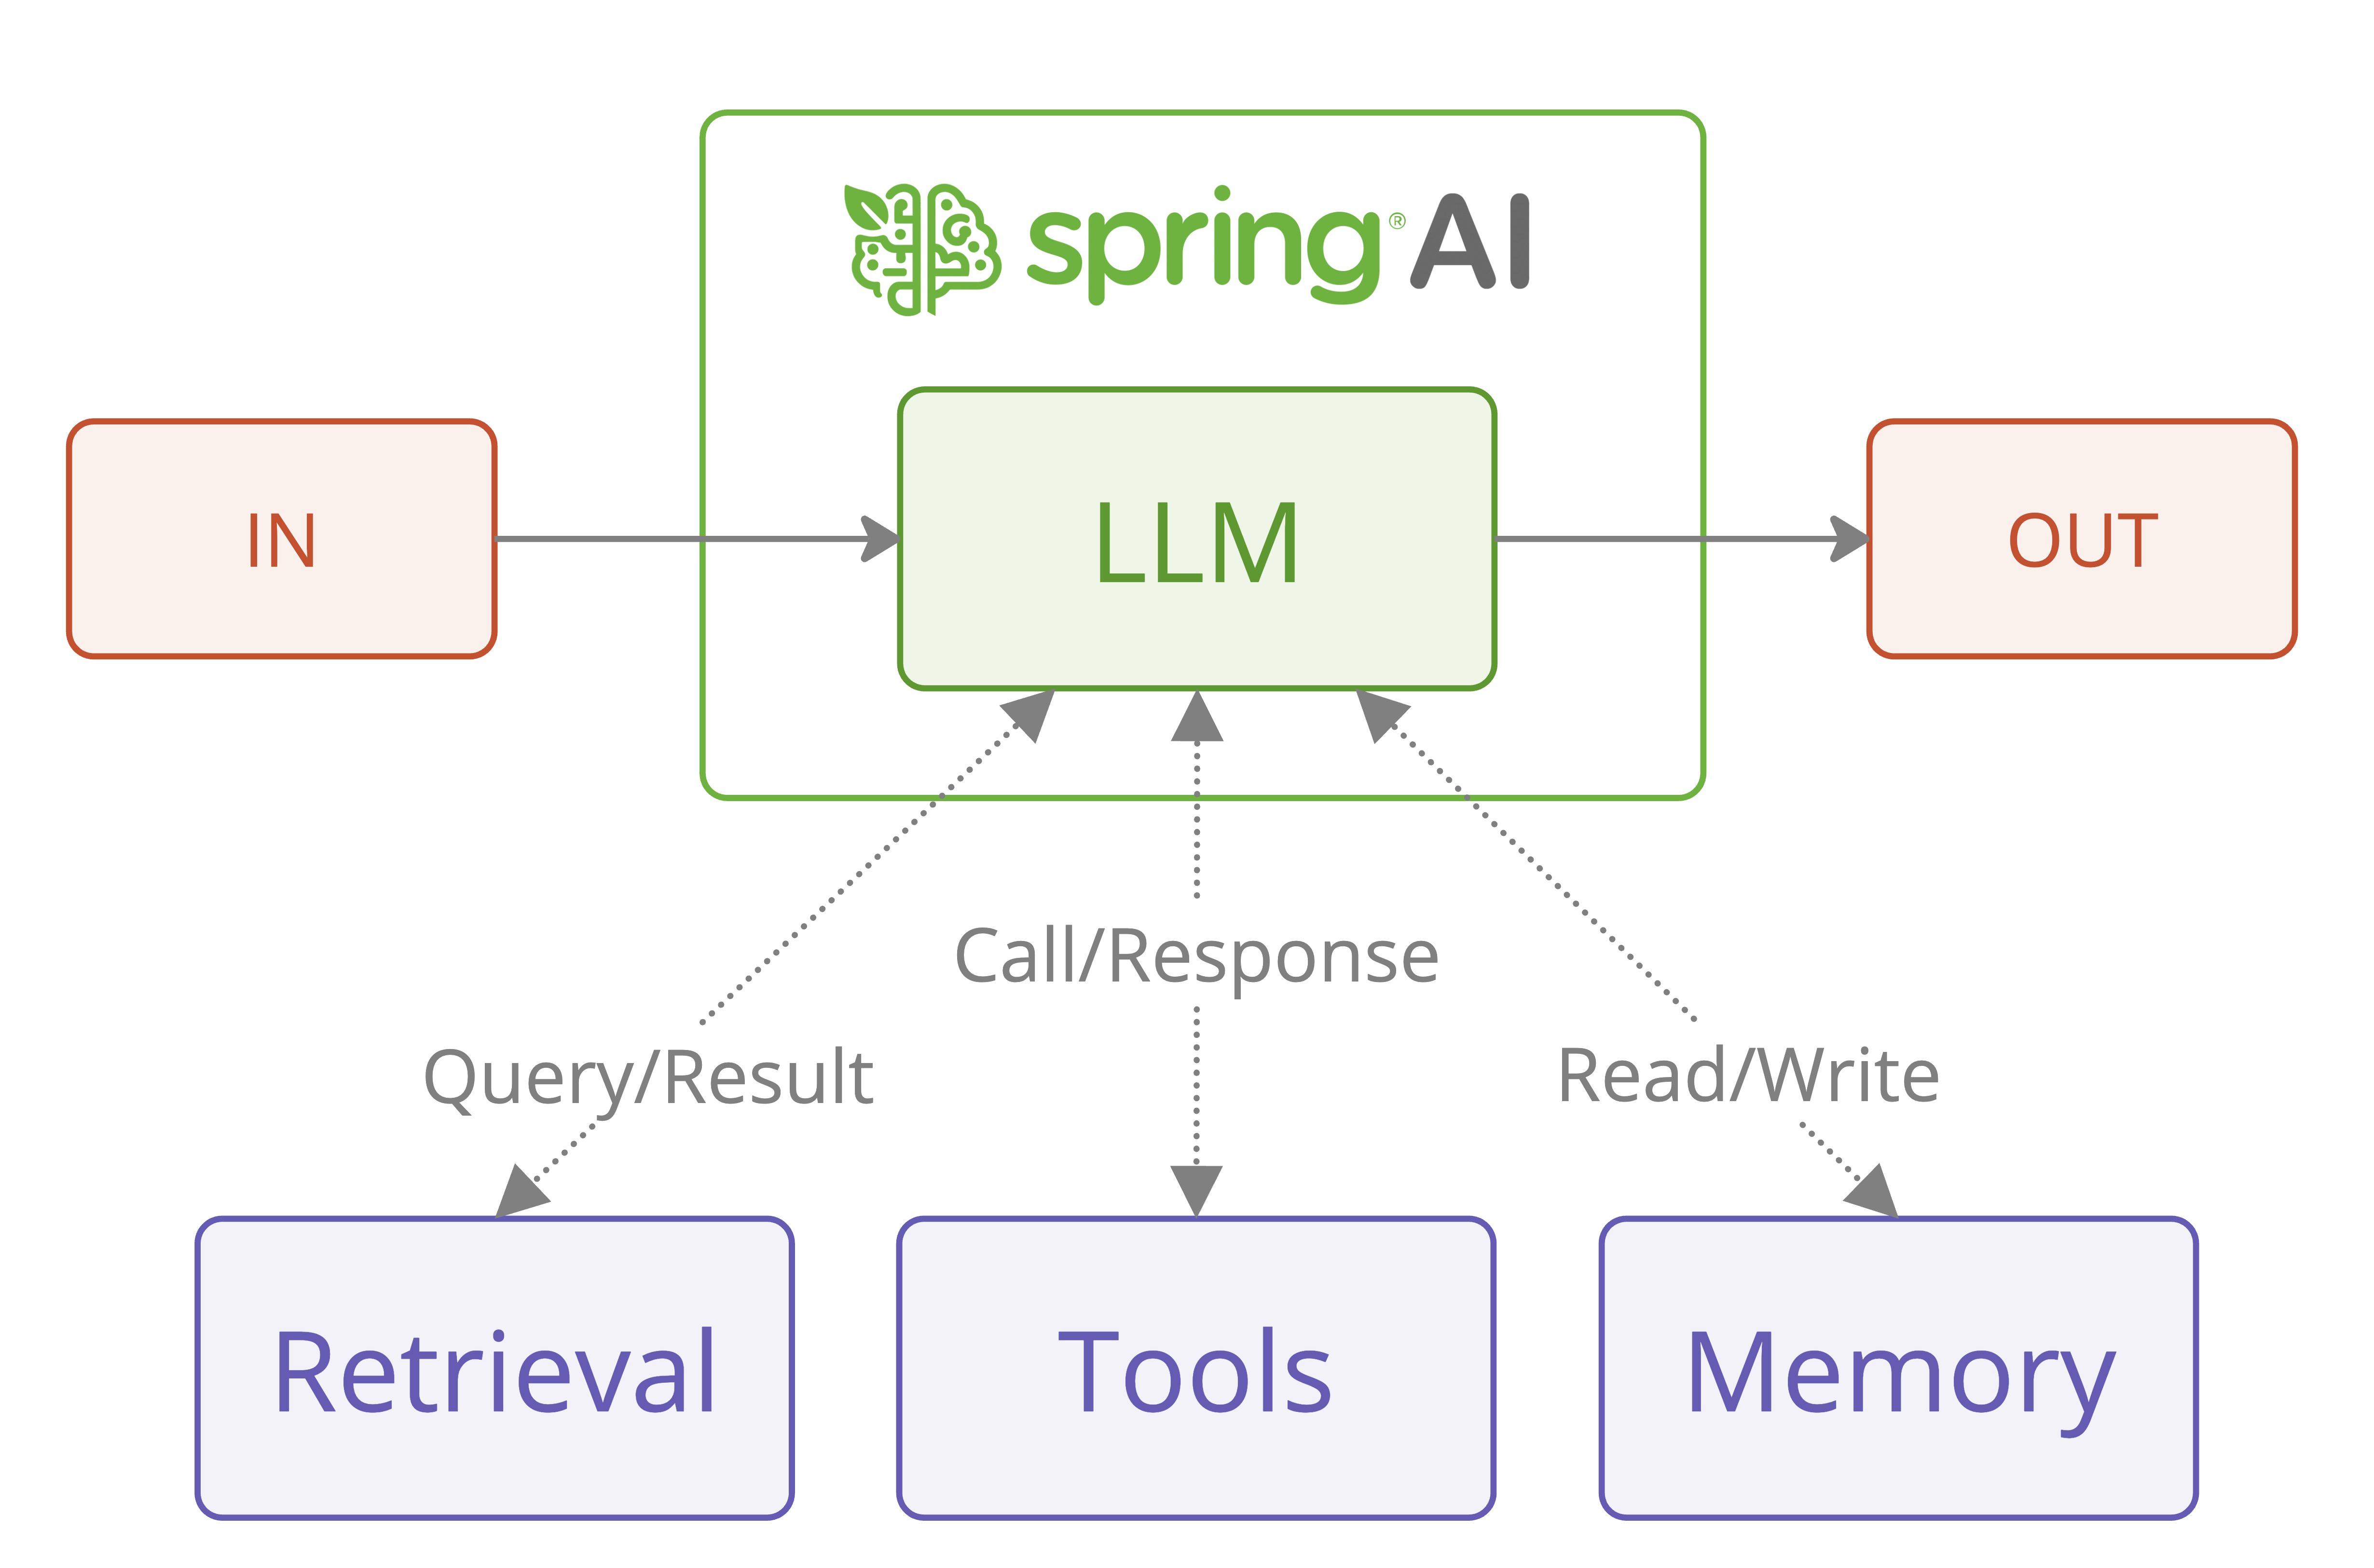
尽管模式描述和图示来源于 Anthropic 的原始出版物,但我们将重点关注如何使用 Spring AI 的功能来实现这些模式,以实现模型的可移植性和结构化输出。我们建议先阅读原始论文。
spring-ai-examples 仓库中的 agentic-patterns 目录包含了以下示例的所有代码。
智能代理系统
该研究论文在两类代理系统之间做出了重要的架构区分:
- 工作流 :通过预定义的代码路径编排大语言模型(LLM)和工具的系统(例如,规范性系统)
- 智能代理 :在这些系统中,大语言模型(LLM)动态地指导自身的流程和工具使用
关键在于,尽管完全自主的智能体看似很有吸引力,但对于定义明确的任务,工作流通常能提供更好的可预测性和一致性。这与企业环境中可靠性与可维护性至关重要的需求完美契合。
让我们通过五个基本模式来探讨 Spring AI 如何实现这些概念,每个模式都服务于特定的用例:
1. 链式工作流
链式工作流模式体现了将复杂任务分解为更简单、更易管理的步骤的原则。
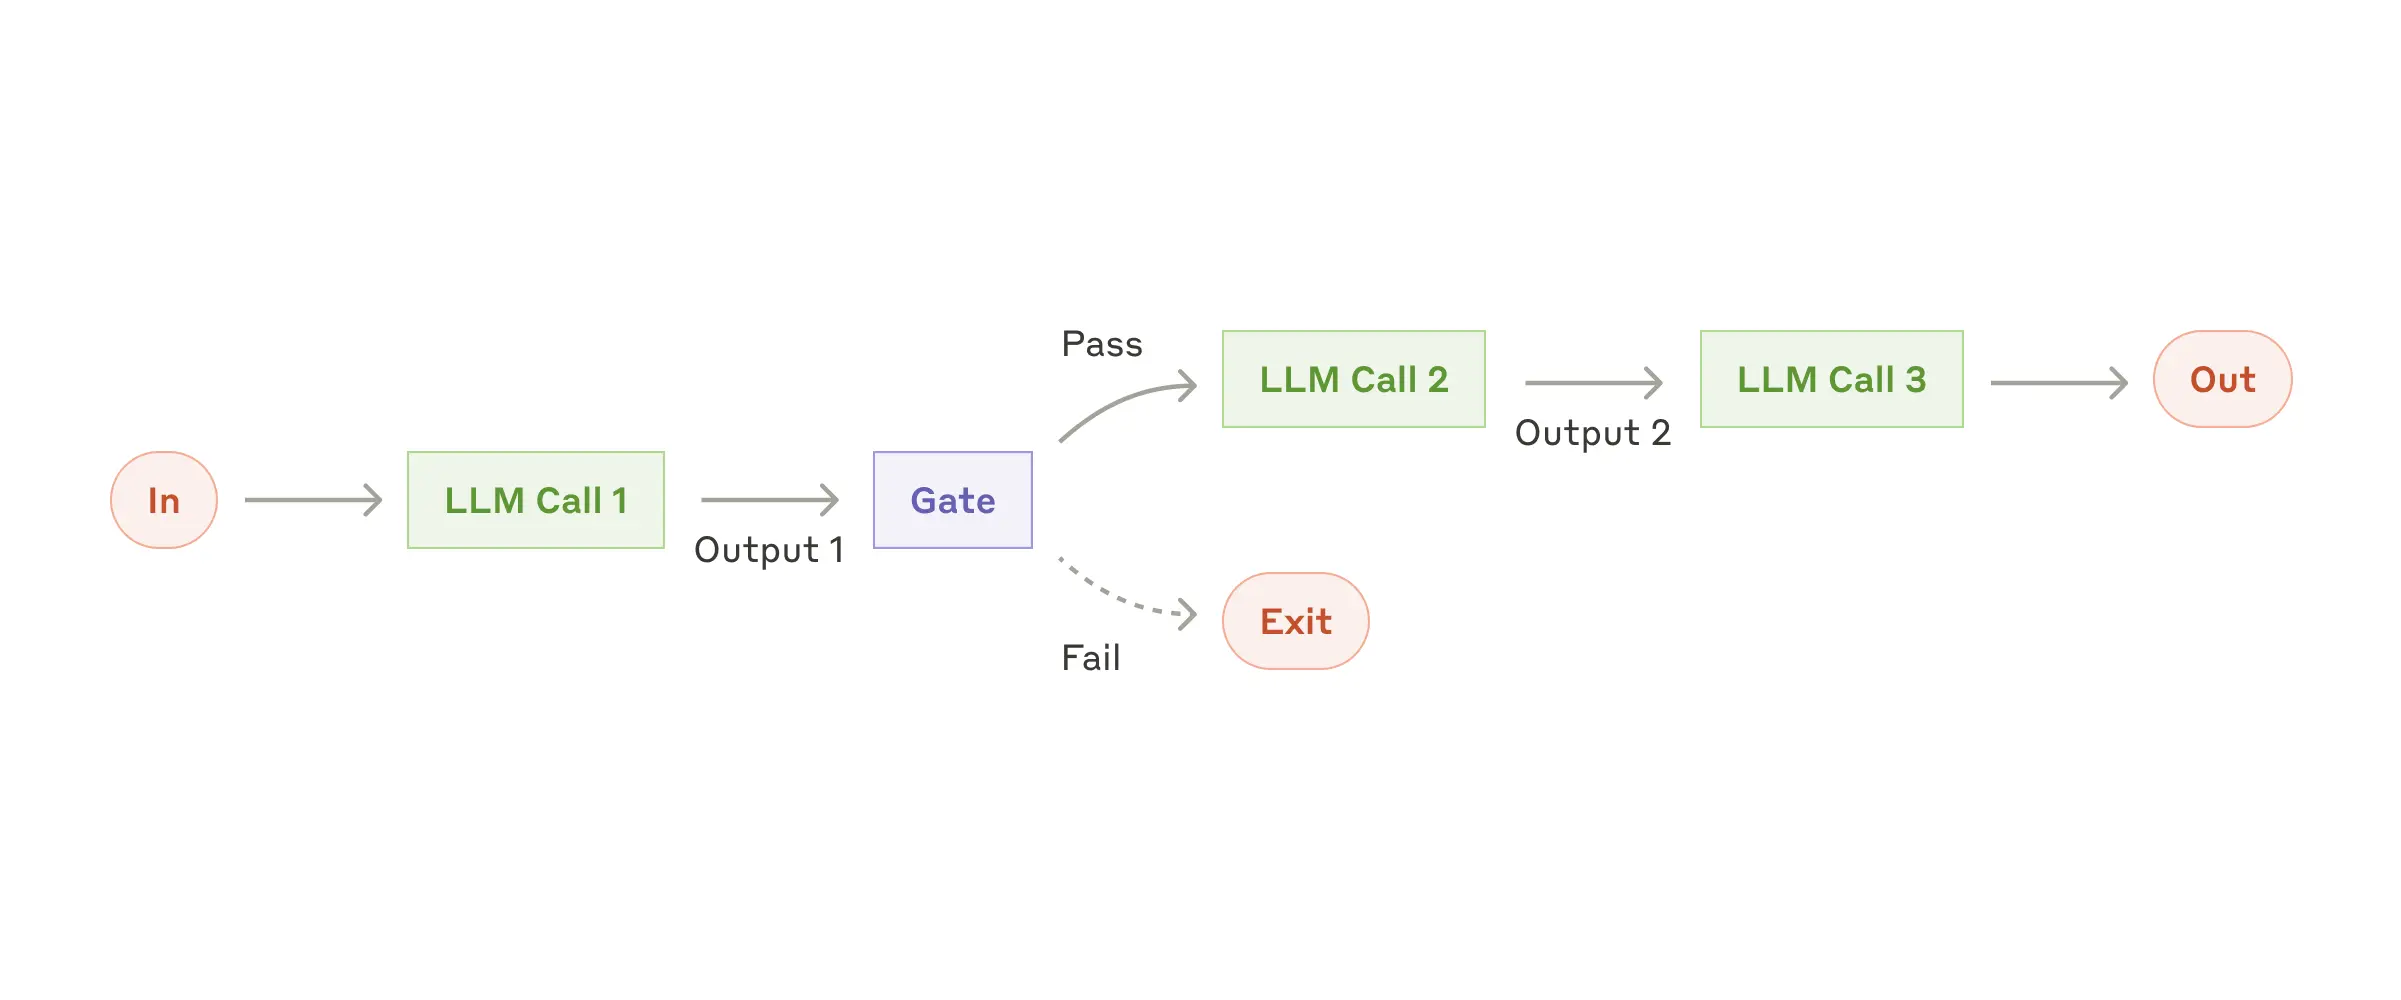
适用场景: - 具有明确顺序步骤的任务 - 当您希望以延迟换取更高准确性时 - 当每个步骤都基于前一步骤的输出时
以下是来自 Spring AI 实现的一个实际示例:
java
public class ChainWorkflow {
    private final ChatClient chatClient;
    private final String[] systemPrompts;

    public String chain(String userInput) {
        String response = userInput;
        for (String prompt : systemPrompts) {
            String input = String.format("{%s}\n {%s}", prompt, response);
            response = chatClient.prompt(input).call().content();
        }
        return response;
    }
}
此实现展示了几个关键原则:
- 每个步骤都有明确的职责
- 上一步的输出成为下一步的输入
- 该链易于扩展和维护
2. 并行化工作流
大型语言模型可以同时处理任务,并通过编程方式聚合其输出。
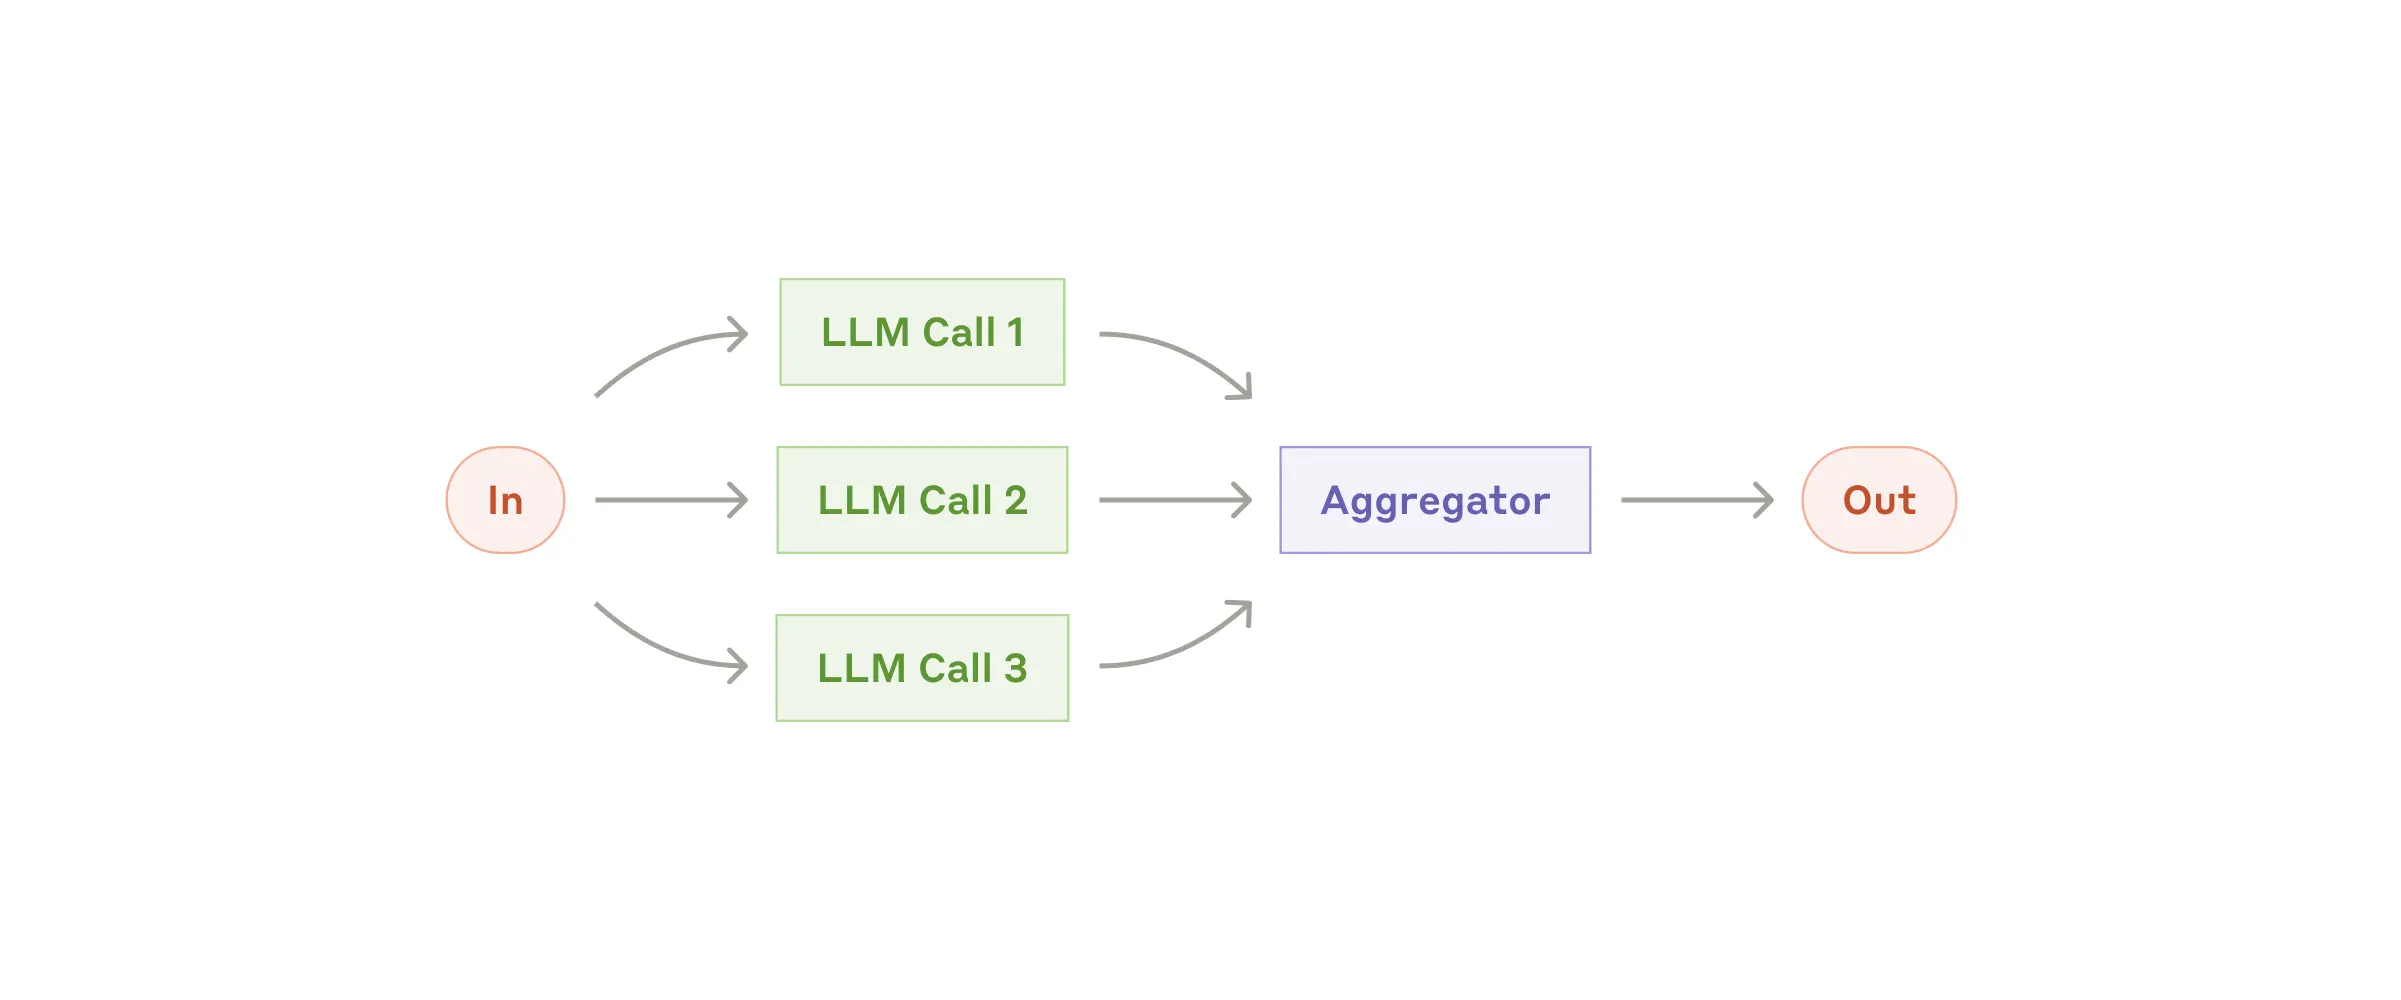
适用场景: - 处理大量相似但相互独立的项目 - 需要多个独立视角的任务 - 处理时间至关重要且任务可并行化时
java
List<String> parallelResponse = new ParallelizationWorkflow(chatClient)
    .parallel(
        "Analyze how market changes will impact this stakeholder group.",
        List.of(
            "Customers: ...",
            "Employees: ...",
            "Investors: ...",
            "Suppliers: ..."
        ),
        4
    );
3. 路由工作流程
路由模式实现了智能任务分配,能够针对不同类型的输入进行专门处理。
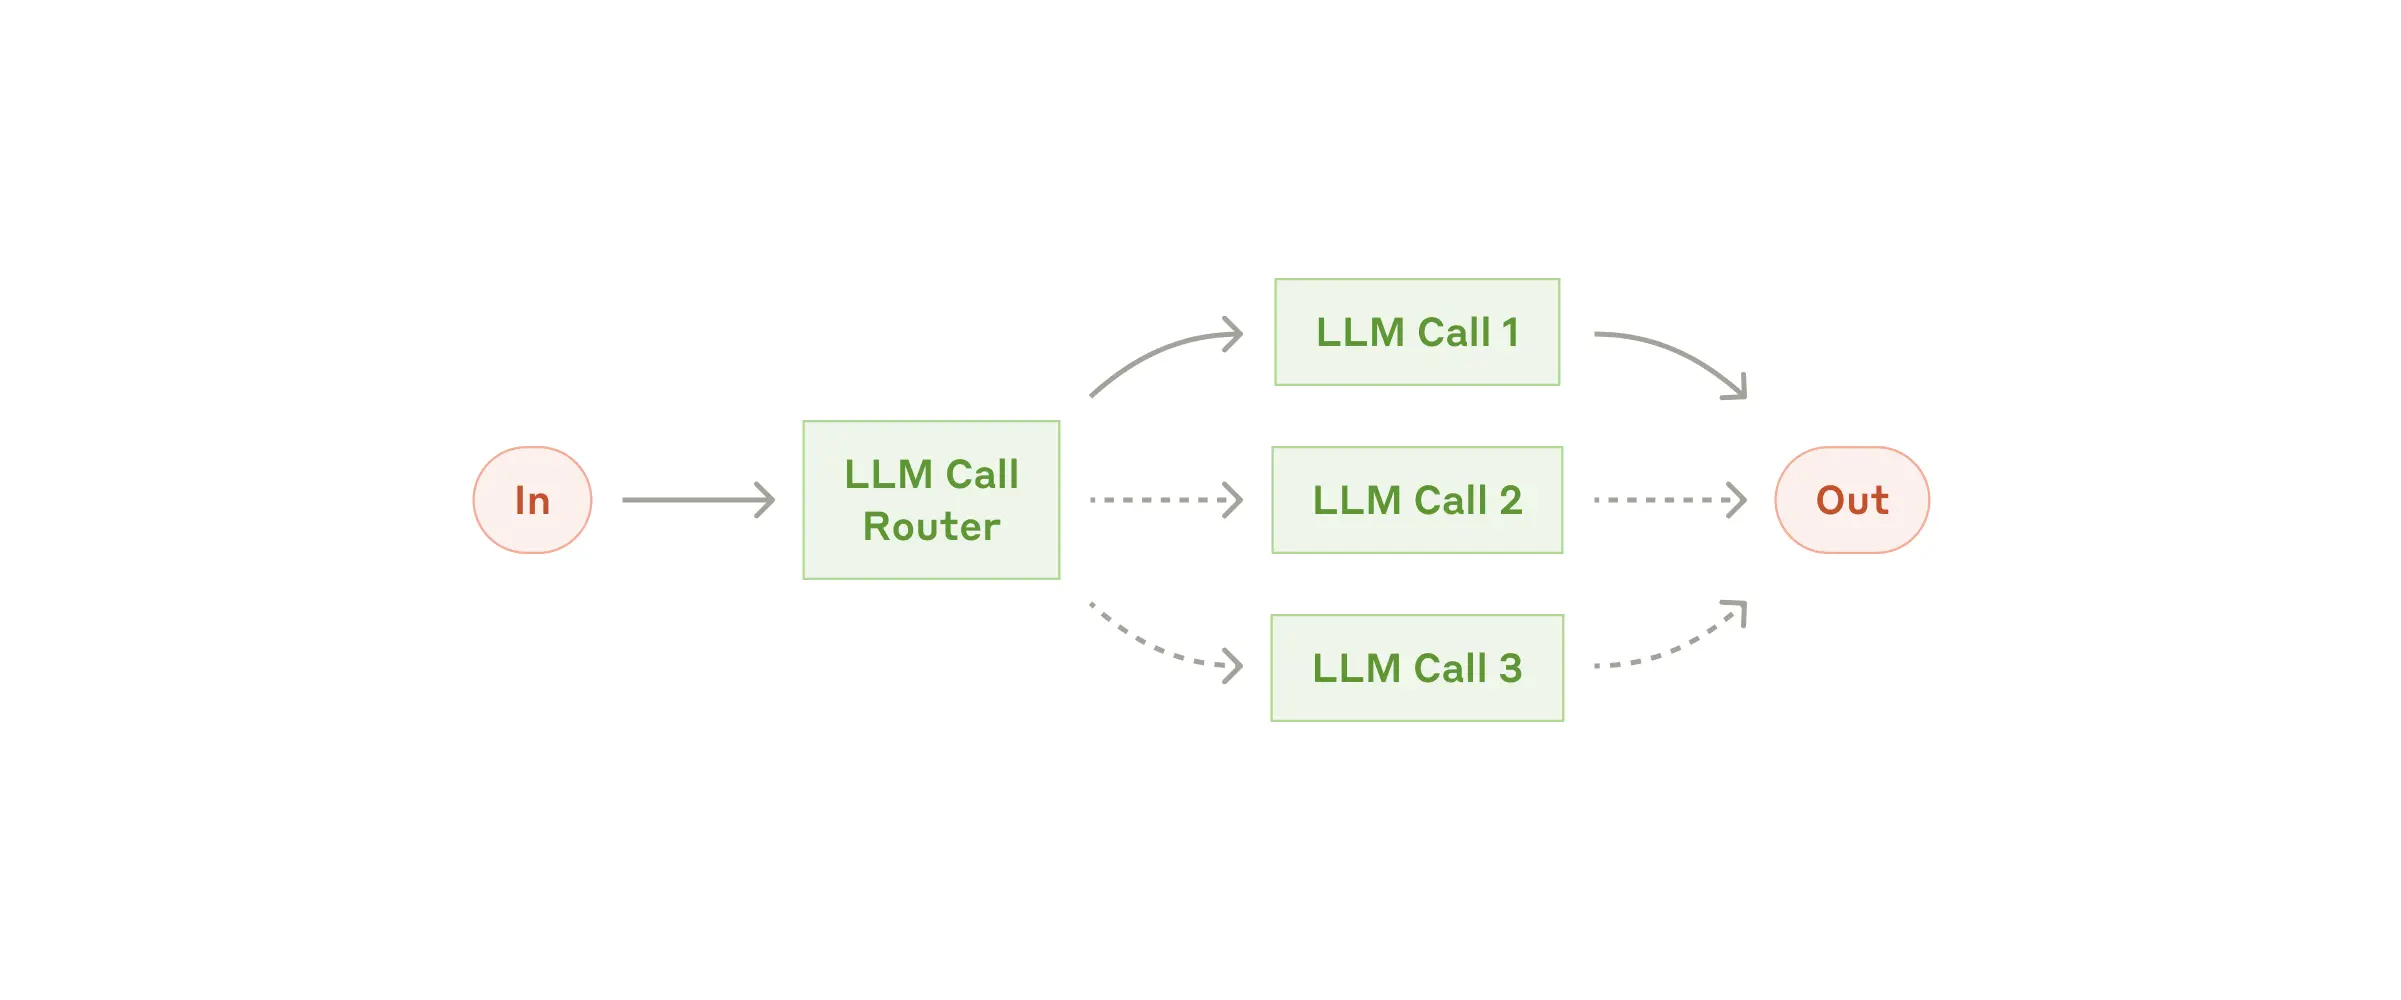
适用场景: - 具有不同类别输入的复杂任务 - 不同输入需要特殊处理时 - 分类可以被准确处理时
java
@Autowired
private ChatClient chatClient;

RoutingWorkflow workflow = new RoutingWorkflow(chatClient);

Map<String, String> routes = Map.of(
    "billing", "You are a billing specialist. Help resolve billing issues...",
    "technical", "You are a technical support engineer. Help solve technical problems...",
    "general", "You are a customer service representative. Help with general inquiries..."
);

String input = "My account was charged twice last week";
String response = workflow.route(input, routes);
4. 编排器-工作节点
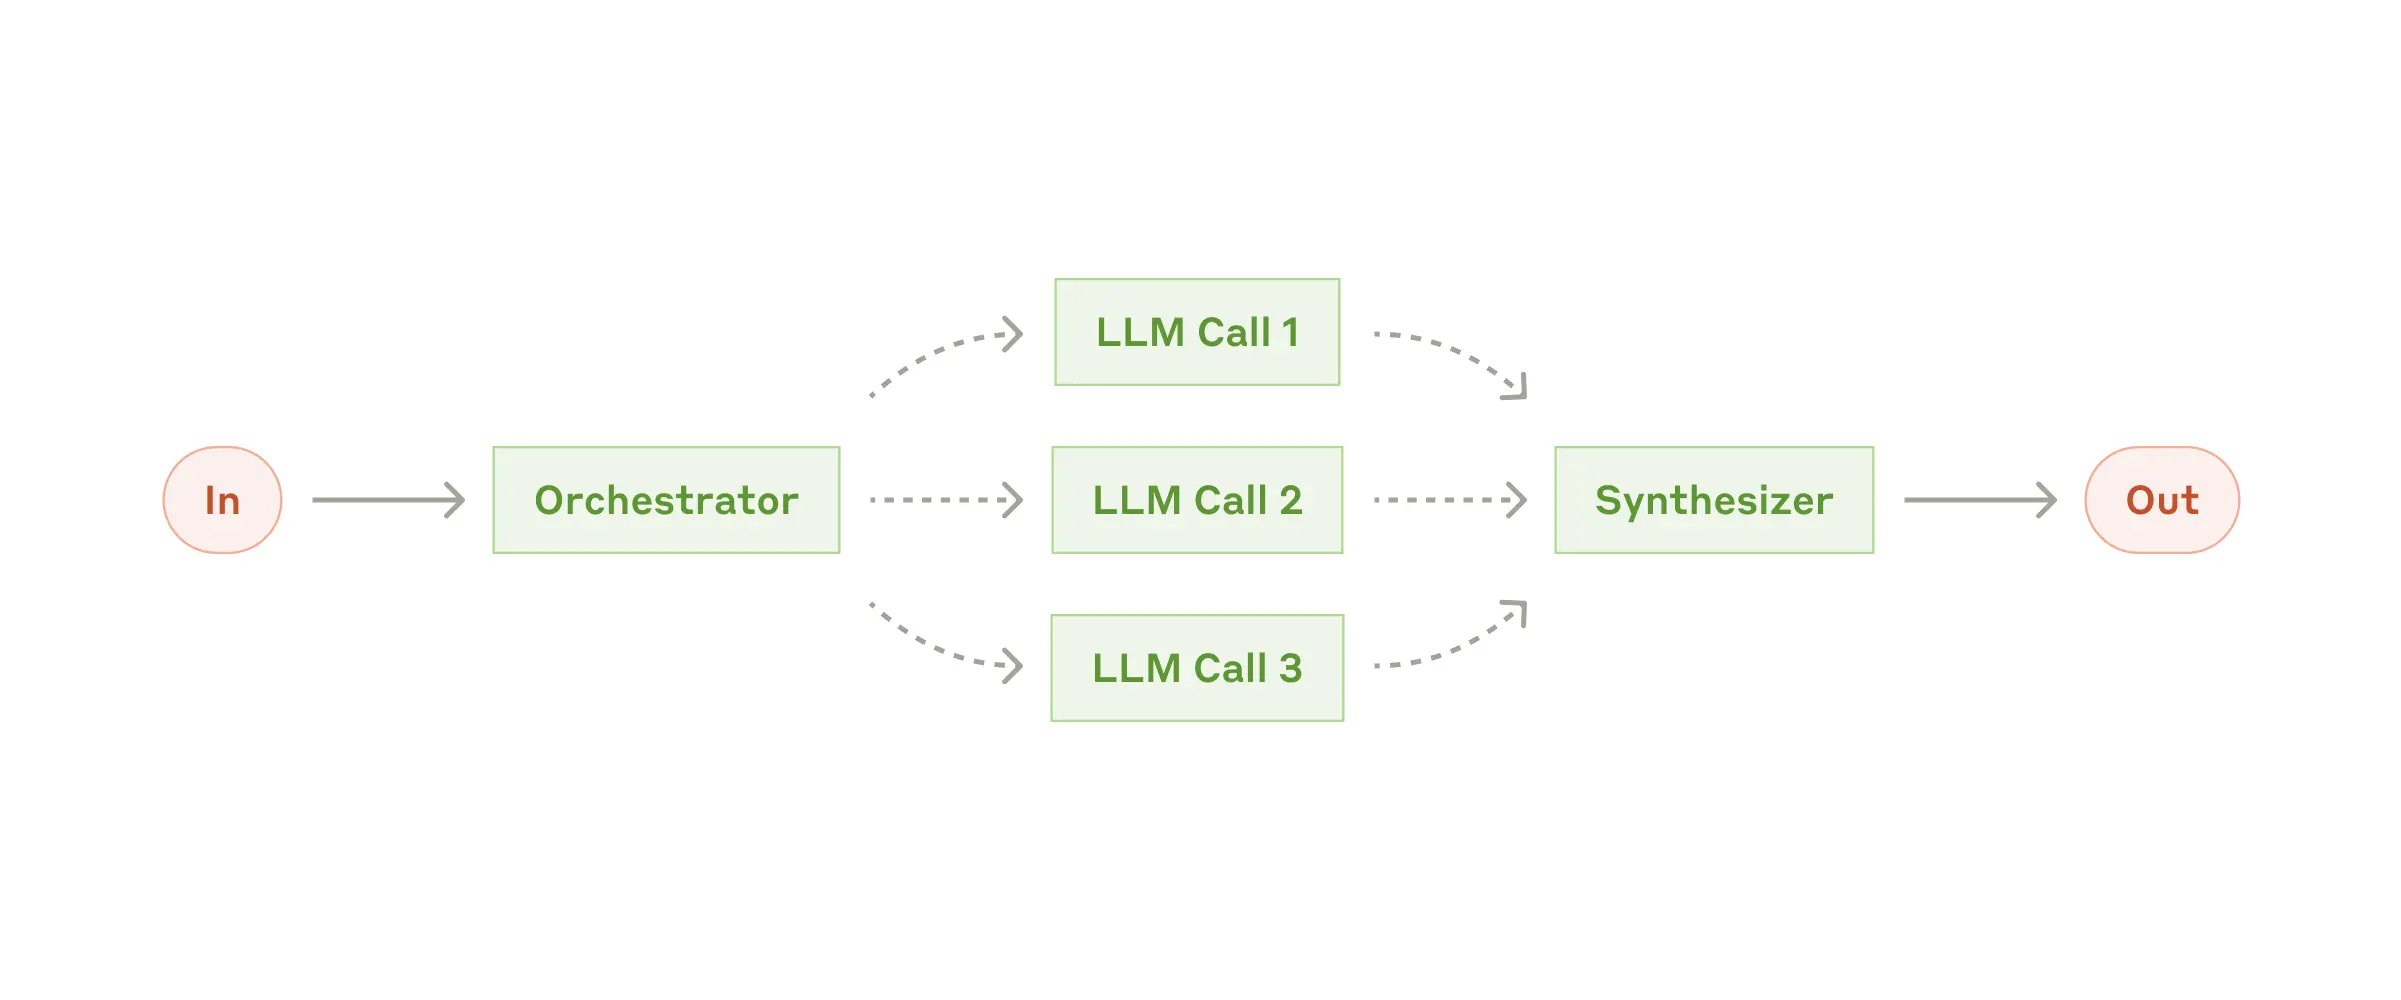
适用场景: - 复杂任务,且子任务无法预先确定 - 需要采用不同方法或视角的任务 - 需要自适应解决问题的情况
java
public class OrchestratorWorkersWorkflow {
    public WorkerResponse process(String taskDescription) {
        // 1. Orchestrator analyzes task and determines subtasks
        OrchestratorResponse orchestratorResponse = // ...

        // 2. Workers process subtasks in parallel
        List<String> workerResponses = // ...

        // 3. Results are combined into final response
        return new WorkerResponse(/*...*/);
    }
}
使用示例:
java
ChatClient chatClient = // ... initialize chat client
OrchestratorWorkersWorkflow workflow = new OrchestratorWorkersWorkflow(chatClient);

WorkerResponse response = workflow.process(
    "Generate both technical and user-friendly documentation for a REST API endpoint"
);

System.out.println("Analysis: " + response.analysis());
System.out.println("Worker Outputs: " + response.workerResponses());
5. 评估器-优化器
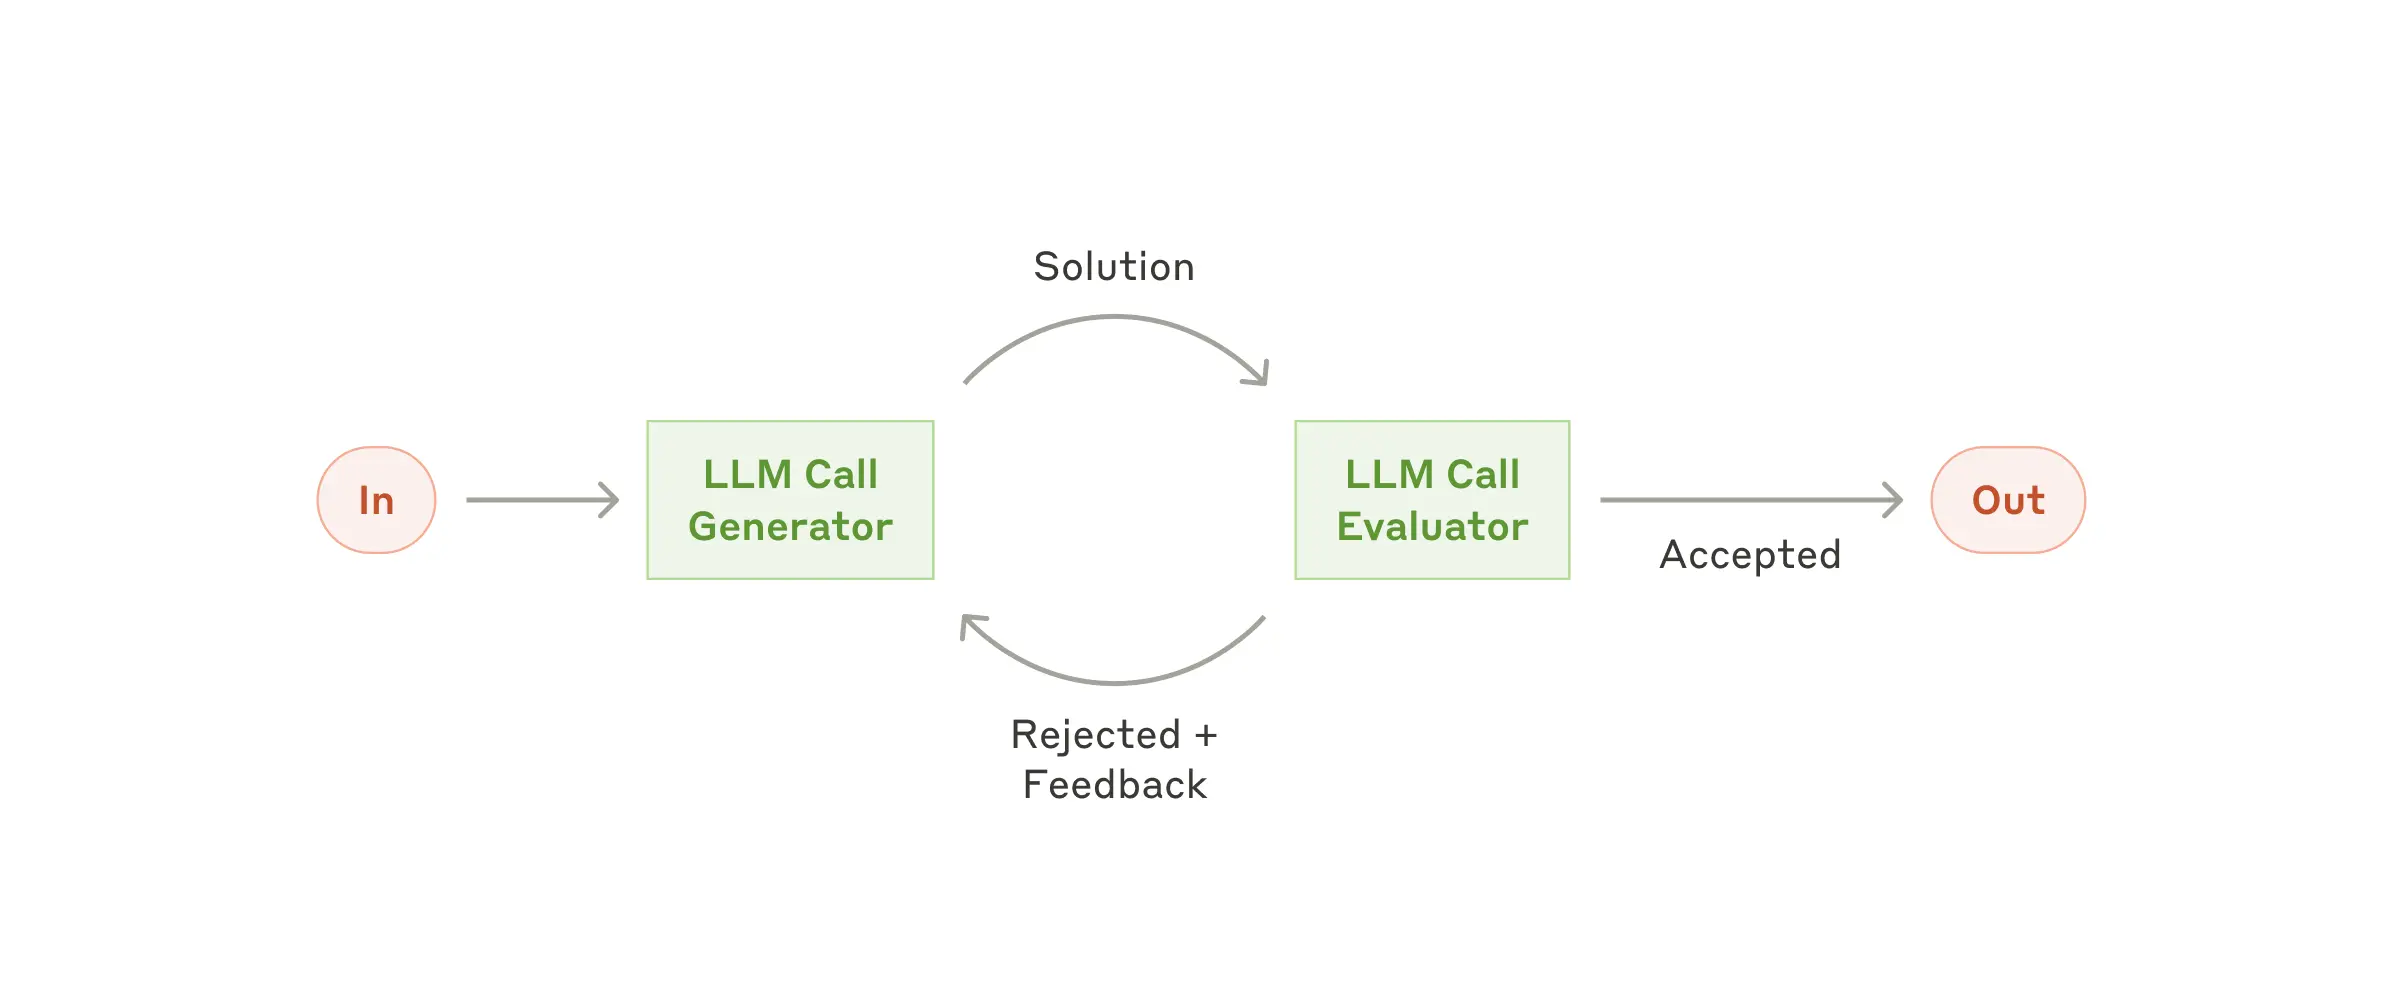
适用场景: - 存在明确的评估标准 - 迭代优化能带来可衡量的价值 - 任务能从多轮评审中受益
java
public class EvaluatorOptimizerWorkflow {
    public RefinedResponse loop(String task) {
        Generation generation = generate(task, context);
        EvaluationResponse evaluation = evaluate(generation.response(), task);
        return new RefinedResponse(finalSolution, chainOfThought);
    }
}
使用示例:
java
ChatClient chatClient = // ... initialize chat client
EvaluatorOptimizerWorkflow workflow = new EvaluatorOptimizerWorkflow(chatClient);

RefinedResponse response = workflow.loop(
    "Create a Java class implementing a thread-safe counter"
);

System.out.println("Final Solution: " + response.solution());
System.out.println("Evolution: " + response.chainOfThought());
Spring AI 的实现优势
Spring AI 对这些模式的实现提供了多项优势,与 Anthropic 的建议相一致:
模型可移植性
xml
<dependency>
    <groupId>org.springframework.ai</groupId>
    <artifactId>spring-ai-openai-spring-boot-starter</artifactId>
</dependency>
结构化输出
java
EvaluationResponse response = chatClient.prompt(prompt)
    .call()
    .entity(EvaluationResponse.class);
一致的 API
- 不同大语言模型提供商之间的统一接口
- 内置的错误处理和重试机制
- 灵活的提示词管理
最佳实践和建议
- 从简单开始
- 先从基本的工作流程开始,再逐步增加复杂性
- 使用满足您需求的最简单模式
- 仅在需要时增加复杂性
- 可靠性设计
- 实现清晰的错误处理
- 尽可能使用类型安全的响应
- 在每一步中内置验证
- 考虑权衡
- 在延迟与准确性之间取得平衡
- 评估何时使用并行处理
- 在固定工作流和动态代理之间进行选择
未来工作
这些指南将不断更新,以探讨如何构建更高级的智能体(Agents),将这些基础模式与复杂功能相结合:
模式组合 - 组合多个模式以创建更强大的工作流 - 构建利用每种模式优势的混合系统 - 创建能够适应不断变化需求的灵活架构
高级代理内存管理 - 实现跨会话的持久性内存 - 高效管理上下文窗口 - 制定长期知识保留策略
工具与模型上下文协议 (MCP) 集成 - 通过标准化接口利用外部工具 - 实现MCP以增强模型交互 - 构建可扩展的代理架构
结论
Anthropic 的研究成果与 Spring AI 的实际应用相结合,为构建高效的基于大语言模型(LLM)的系统提供了一个强大的框架。
通过遵循这些模式和原则,开发者可以创建出健壮、可维护且高效的AI应用程序,在避免不必要复杂性的同时提供真正的价值。
关键是记住,有时最简单的解决方案才是最有效的。从基本模式开始,彻底理解你的使用场景,只有在能够明显提升系统性能或能力时才增加复杂性。
部署到云
Spring 云绑定组件
Spring 云提供基于 Spring 云绑定 的云绑定支持。 这使得应用程序能够指定提供者绑定类型,并使用通用格式表达属性。 Spring 云绑定将处理这些属性并将其绑定到Spring 云属性中。
示例,当使用 OpenAi 时,绑定类型是 openai 。 使用属性 spring.ai.cloud.bindings.openai.enabled ,绑定处理器可以启用或禁用。 由于默认情况下,指定绑定类型时该属性将被启用,因此 api-key 、 uri 、 username 、 password 等等可以进行配置,并且 spring-ai 会将其映射到支持系统中对应的属性。
要启用云绑定支持,请在应用中包含以下依赖项。
xml
<dependency>
   <groupId>org.springframework.ai</groupId>
   <artifactId>spring-ai-spring-cloud-bindings</artifactId>
</dependency>
或者添加到您的Gradle 构建脚本文件 中。
groovy
dependencies {
    implementation 'org.springframework.ai:spring-ai-spring-cloud-bindings'
}| 参考以下 依赖管理 部分,添加Spring AI BOM到你的构建文件中。 |
|---|
Available Cloud Bindings
这些组件中,目前在 spring-ai-spring-cloud-bindings 模块中支持云绑定的组件包括:
| 服务类型 | 绑定类型 | 源属性 | 目标属性 目标属性文件包含将作为目标应用属性值的属性值。 |
|---|---|---|---|
Chroma Vector Store | chroma | uri, username, password | spring.ai.vectorstore.chroma.client.host, spring.ai.vectorstore.chroma.client.port, spring.ai.vectorstore.chroma.client.username, spring.ai.vectorstore.chroma.client.host.password |
Mistral AI | mistralai | api-key, uri | spring.ai.mistralai.api-key, spring.ai.mistralai.base-url |
Ollama | ollama | uri | spring.ai.ollama.base-url |
OpenAi | openai | api-key, uri | spring.ai.openai.api-key, spring.ai.openai.base-url |
Weaviate | weaviate | uri, api-key | spring.ai.vectorstore.weaviate.scheme, spring.ai.vectorstore.weaviate.host, spring.ai.vectorstore.weaviate.api-key |
Tanzu GenAI | genai | uri, api-key, model-capabilities ( chat 和 embedding ), model-name | spring.ai.openai.chat.base-url, spring.ai.openai.chat.api-key, spring.ai.openai.chat.options.model, spring.ai.openai.embedding.base-url, spring.ai.openai.embedding.api-key, spring.ai.openai.embedding.options.model |